
Dyna-2:100万時間の人間動画で学ぶワールドアクションモデルと、1時間自律で動く汎用ロボット — Jason Ma(Dyna Robotics)
Dyna-2: General Purpose Physical Agents with Hour-Long Autonomy — Jason Ma, Dyna Robotics
Dyna-2:100万時間の人間動画で学ぶワールドアクションモデルと、1時間自律で動く汎用ロボット — Jason Ma(Dyna Robotics)
Latent Space: The AI Engineer Podcast
要約
Dyna Robotics 共同創業者でチーフサイエンティストの Jason Ma が、100万時間超の人間動画で学習したワールドアクションモデル「Dyna-2」の仕組みを語った。未来の映像と行動を同時に予測する設計、少量のデモで新タスクを覚える方法、データ不足という課題、自社ハードウェアを作る理由を説明。Din Tai Fung でのナプキン折りなど実運用の事例や、エージェント的ハーネスによる長時間作業、VLA との違いも議論された。
この回のポイント
- ●Dyna-2 は映像と関節角度、言語指示を入力に、未来の映像を予測しつつロボットの行動を出力するワールドアクションモデルで、拡散トランスフォーマーを基盤とする。
- ●ロボットにはインターネットに相当するデータがなく、人間の一人称視点データで事前学習し、少量のロボット自身のデータで適応させる方針をとる。新タスクは数十分〜数時間のデータで学習できると述べている。
- ●推論遅延が許されないためオンデバイスで動かす必要があり、大きなモデルを学習してから蒸留する考え方を示した。推論スタックも自社で構築している。
- ●ハードウェアは自社設計の車輪付き「セミヒューマノイド」。人間の体型に合わせ、人間データからの転移を狙う。一方、ロボットハンドの過熱や触覚などのセンサー不足が大きな制約だという。
- ●Din Tai Fung では1日に数千枚のナプキンを折り、複数店舗に展開している。Jason はこれを、パイロットで終わらない本格導入の例として挙げた。
- ●エージェント的ハーネスで階層的に判断を行い、洗濯ワークフロー全体のような1時間規模の自律作業を実現している。
- ●VLA(視覚言語行動モデル)に対し、人間の偏りを避けて生の映像を予測すべきだと主張。ただし触覚など視覚以外のモダリティが有効なら自分たちが誤る可能性にも言及した。
章立て
ワールドアクションモデルとは
Dyna-2 の入力・出力と、未来の映像予測で行動を導く発想を説明する。
拡散トランスフォーマーと汎用モデル
拡散と Flow Matching の役割、汎用の基盤モデルを少量のデモで微調整するアプローチを語る。
データ不足と合成データ
ロボットにインターネットがない問題、人間データとロボットデータの組み合わせ、シミュレーションと自己生成データの可能性を議論する。
オンデバイス推論と自社ハードウェア
低遅延の必要性、蒸留、推論スタック、アクチュエータやサプライチェーン、車輪式セミヒューマノイドの設計を説明する。
評価・タスク学習とボトルネック
新タスクの学習と評価の流れ、1時間規模のタスク、ハンドの過熱やセンサー不足といった制約を述べる。
顧客事例とロボティクスのBitter Lesson
Best Western や Din Tai Fung での導入と、特化型ではなく汎用モデルをスケールさせる考え方を語る。
エージェントハーネスと VLA との違い
長時間作業のための階層的な仕組み、コーディングエージェントの活用、ワールドアクションモデルと VLA の比較を行う。
経歴・組織文化・ビジョン
AlphaGo から Eureka、創業までの経緯、製品志向の文化、社名の由来、数百〜数百万台への展望を語る。
解説記事
Latent Space の収録で、Dyna Robotics 共同創業者でチーフサイエンティストの Jason Ma が、同社の最新モデル「Dyna-2」と、実運用を重視するロボット開発の考え方を語った。100万時間超の人間動画で学習したワールドアクションモデルが中心の話題で、データ、ハードウェア、実導入まで幅広く議論されている。
未来を予測して行動するワールドアクションモデル
Dyna-2 は、未来の映像(世界の状態)を予測しつつ、ロボットが実行する行動も出力するモデルだ。入力は過去数秒の映像、関節角度、言語指示である。Jason は、人間が行動の結果として世界がどう変化するかを頭の中で想像していることになぞらえ、視覚・物理の空間で推論してから行動を出す設計だと説明した。これにより、動きが器用で頑健になり、未知の環境にも一般化しやすくなると述べている。
基盤は拡散トランスフォーマーである。拡散モデルはノイズから精緻な出力を段階的に作る手法で、画像の鮮明さと同様に、ロボットの行動にも滑らかさと精密さが求められるという。Flow Matching は拡散の特殊で調整しやすい変種だと位置づけた。行動空間は連続の約100次元で、毎秒10〜20回の予測を行い、直近の文脈も参照している。
データが最大の課題
Jason は、ロボット工学にはインターネットに相当するものがなく、データが最重要の課題だと強調する。自社収集だけでは不十分で、データの購入や既存データの活用が必要になる。そこで人間の一人称視点の映像で幅広い物理的な事前知識を学ばせ、人間とロボットの動作差は少量のロボットデータで埋めるという方針をとる。新タスクは数十分から数時間のデモで学習でき、試験運用で性能が7〜8割程度なら追加データで改善する。これをロボット版の人間フィードバック強化学習のようなものだと述べた。
次のスケーリングの軸として期待するのが合成データだ。博士課程で GPT-4 に報酬関数を書かせた Eureka を例に、当時は限界があったが、現在のフロンティアモデルは3D再構成などの視覚能力が高く、転換点にあると見ている。自社のワールドアクションモデルが自ら学習データを生成する循環も構想している。
自社ハードウェアとオンデバイス推論
ロボットは数秒の遅延も許されないため、モデルはオンデバイスで動かす必要がある。大きなモデルを学習して蒸留する流れが収束先だとし、推論スタックも自社で構築している。ハードウェアも、LiDAR のように成熟した部品は購入し、性能に直結するアクチュエータなどは自社で作る方針だ。体型は人間の比率に合わせて測定されており、人間データからの転移を意識している。
形状は上半身がヒューマノイド、下半身が車輪の「セミヒューマノイド」。脚式は消費エネルギー、不安定さ、安全性の保証が難しいと説明した。腰の自由度を持たせたのも、人間が無意識に胴体を使うためだ。希土類磁石など供給網の長さにも触れ、ハードウェアの難しさは過小評価されていると述べた。
実導入とBitter Lesson
最大の顧客事例が Din Tai Fung で、複数拠点で1日に数千枚のナプキンを折っている。Jason は、パイロットを行う企業は多いが、顧客が価値を認め複数拠点に展開する段階に進むのは難しく、自社はそこに到達していると主張する。布のような変形物は構成が無限にあり、専用機より汎用モデルの適応のほうが早く品質に達するという。全ロボットへ重みを一括更新できるため、拠点間の品質のばらつきも抑えられる。
ロボット版 Bitter Lesson として、特殊な事前知識を組み込むより、単純なアルゴリズムで適切なデータをスケールさせるべきだと述べた。難しいのは、どのセンサーでどのデータを取るかを決めることだとする。
長時間自律とVLAとの違い
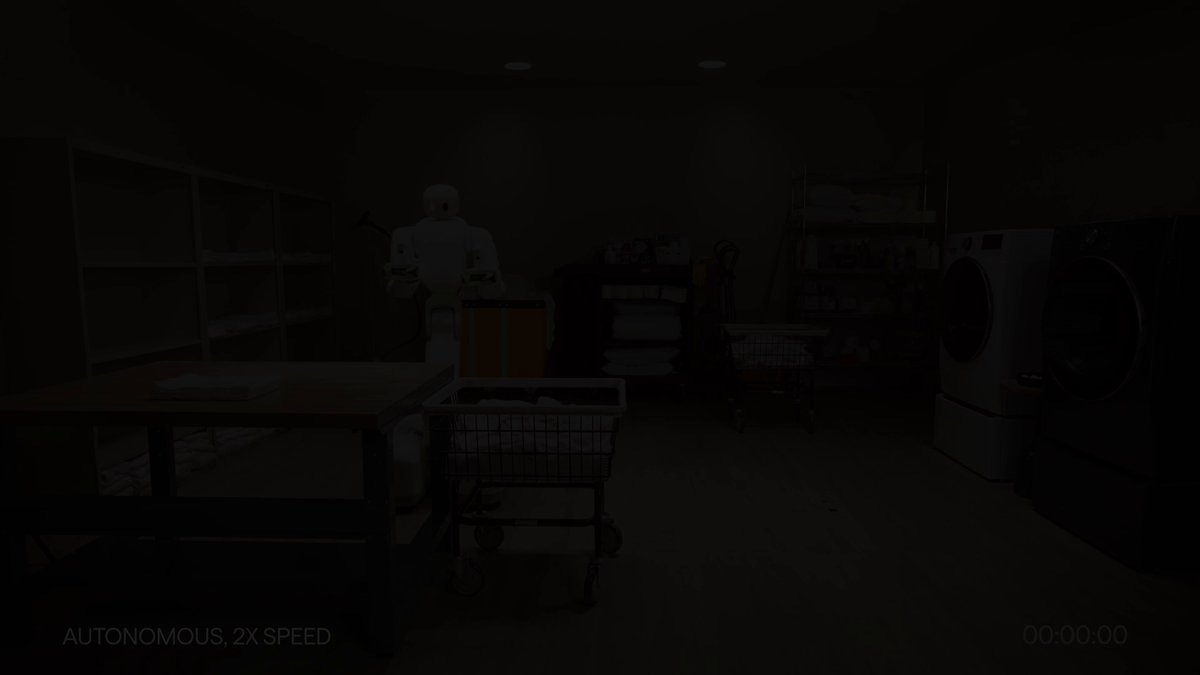
洗濯ワークフロー全体は約1時間で、洗濯機が回っている間に別作業を行うなど高レベルの判断が必要になる。これを低レベルのモデルだけで学ぶのは非効率なため、ワールドアクションモデルの周りにエージェント的ハーネスを置く階層構造で対応している。価値は1分程度のタスクではなく、数時間監督なしで続く業務にあると述べた。
VLA との違いについては、抽象的な表現を予測すると人間のバイアスが入るため、カメラ入力に近い生の表現を予測するほうがよいという立場を示した。ただし、触覚など映像以外のモダリティのほうがデータ効率が高い可能性があり、そこが自分たちの誤りうる点だとも認めている。当面のボトルネックは、耐久性のあるロボットハンドと、視覚以外のデータの欠如だという。
まとめ
本エピソードは、ロボット基盤モデルをデモで終わらせず、ハードウェアから顧客導入までを一体で回す企業の視点を示している。日本の読者にとって注目点は三つある。人間の一人称動画をロボット学習に活かす発想、少量のデモで適応する汎用モデルという製品戦略、そして実導入で見える真のボトルネック(ハンドの耐久性、触覚データ)だ。来年は数百台規模への展開を目指すとのことで、実運用の成果が今後の指標になるだろう。
文字起こし(英語・自動生成)
All right, we're here on site with Jason Ma, co-founder and chief scientist of Dyna Robotics. Thanks for having us in your studio. Of course. Thank you for coming. Yeah, it's been a blast. We got to see, you'll see a lot of V-Robo, we got to see drinks being pulled, a lot of evals, robots with knives for the first time. So under the hood of all this, you have a world action model. What is that? Yeah, so last month we released our world action model called Dyna2. So it's the first world action model trained on more than one million hours of data. So going back to your question first, world action model is the model that's able to predict the future video, the future state of the world. So hence the name world model. But in addition, you can also use that future generation to also produce actions robots can execute in the physical world to control the robot. So why do we do that? It's a very powerful architecture. because if you think about how humans act in the physical world, in our brain, we're implicitly thinking about how the world will evolve based on our actions.
So now we have a model architecture that's able to do that to guide robot actions. So what we find is that by doing so, the model is much more dexterous, much more robust, and much more capable of generalizing to environments, to scenarios it's never seen before. Yeah. I want to prompt this question a bit. I think a lot of people hear world model and they think you're outputting video or world or 3D state. You're also doing action. I think most people don't understand what models are under the hood of robotics. So what is input, output? What's the training data? What is the architecture? Give us all the details. Yeah. So for inputs, the most important input is video. Right. You know, you can think about videos that the robot is capturing with its cameras. Right. So video or images of the past many seconds, that's the input. But for robots, what's really interesting is that robot also has a lot of actuator, a lot of joint encoders on itself. So the robot also knows the angles of its joints.
So those can also be inputs to this world model. That's something that's very different from just a pure video model that's only looking at videos, right? So that's the input. And additionally, for robots, you want to be able to talk to it, to instruct it, to do different tasks, right? So you can also feed it like language instruction. So those are what I consider the basic set of inputs that go into any robotics models, including world action models. And once we have that, the output, at the basic level, it needs to output actions the robots can execute on the hardware. But in the case of world action model, what's really interesting is that in addition to the actions, we can also output future video, right? So basically, you can almost output the future video or some representation of it first, and then use that to guide robot actions. So the way I think about it is like, this is kind of analogous to, you know, Chang'e's thought, you know. Basically, the models are reasoning in the visual, the physics space, and then outputting actions. So that's the key difference
between world action models outputs versus other kind of models, robot models outputs. You put out a good blog post around your model. I think a lot of people understand language models or transformers, next token predictors. In this case, you shared quite a bit. There's like diffusion, flow matching, you're predicting next world state plus action. One thing you say is a million hours. How do you determine the architecture? Like what are the choices there? What is the architecture? I feel like in language models, there's a lot of take something off the shelf, take trillions of tokens, do prediction, SFT, RL, and you have a model. What about this? How do you go from nothing to your model? Is there vanilla architecture off the shelf? Do you determine all this? And what is the current state? Yeah, I think, yeah. So the mental framework to think about how do we build models for robotics is that there are essentially a couple of things to look at. One is data. And the second is like, how do we make a model learn as much as possible
from that data? So let's first talk about the model actually, right? So the blog post we released is our Dyna 2 word action model. So under the hood, it's a diffusion transformer. So transformer is essentially like the language model, you know, sequence to sequence, mass, recorder only. But what's really interesting is that in visual domains, right, if you think about generating images, generating videos, and in this case, robots looking at images to generate actions, people have found the diffusion kind of architecture to work really well. So what is a diffusion model? A diffusion model is a model that takes some random noise and through iterative computation can go from noise to something that's really high dimensional and that's something really highly defined and have very fine-grain feature. If you think about generating images, you want sharp edges, sharp corners, color contrast. And for robotics, even though you're not generating image, you're generating actions that needs to be very precise, very smooth.
So it has kind of this same kind of consideration of desiderata as generating image. So that's why, from first principle, the whole field, not just us, have been using this kind of diffusion transformer architecture to train robotics foundation models. You need the transformer aspect because transformer is the thing that can just ingest the most amount of data, can learn. Then diffusion helps you to refine the outcome, to get to the smooth, precise, fine-grained motion you need to actually execute on the robot. So that's the architecture that goes behind a lot of our recent breakers. And we've covered flow matching before on the podcast. It is mostly an efficiency speed up. Like, let's say normally it would take 40 to 100 diffusion steps. You can reduce it to four. Yeah, that's right. So with a diffusion model, one thing that's really hard in practice is that you need to tune the scheduler. Like, by how much you're tuning or converting the initial noise input into the final output. So flow matching is kind of a special case of diffusion
that makes the transformation much simpler. In practice, you don't have to tune as much, and it works just as well. That is why I think about two to three years ago, most generative modeling for image and video has shifted from a diffusion model to a flow matching model. But the concept is the same, and flow matching is just a special, simpler-to-tune variant of diffusion. It actually makes me think that... So flow matching obviously has trade-offs in quality, but actually it's very suited for action diffusion and robotics because you get to re-evaluate in real time. Whereas in images, it's basically one shot. That's right. Which is pretty fun. We got to mess with the laundry folding robot, like throw a random towel in, the models adapt, right? I think one key thing about your models is that they're made to be generalists, so one foundation model and you adapt them a lot. How does that work? Basically, in 45 minutes of mapped data, you can generalize towards, we saw an example of pulling drinks out of a fridge.
What's the mindset there of one general model, and then how do you adapt to different tasks? Yeah, so the way we think about it is that for robotics, we need to build a very general, strong base model. Right. And then because if you think about how a human interacts and behaves in a physical world, right, we have very strong base knowledge. We can just readily do a lot of tasks. But if you want to become an expert at any given task, there is some amount of training that needs to happen. And I think to train a general purpose robot like the one we're building here, the same principle has to apply. So our approach is to first train a general model that's training on as much data as we can find. So that is when our data to report, our model is trained over a million hours of human data as a starting point. And then given that strong foundation, what we found is we can quickly make the robot or make the model do many, many different tasks with a very minimal amount of fine tuning to just tell the model, here's the task I want it to do.
And here's very few amount of demonstrations. And the model can readily do a bunch of the tasks that you have in the office. We actually have quite a few people who deal in data, who sell data. What is good data? What is bad data? What do you want to buy? I think these are all open questions. Obviously, I think the top important thing is egocentric data of humans doing tasks. What else would you modify on that basic statement? Yeah, yeah. So I think data is the most important thing in robotics today. because unlike language model, there is no internet, right? So every company that's building model, building hardware, has to think about data. So there's roughly a couple of different ways of operating here. One is that you can collect a lot of data yourself, which is what we are doing as... You have employees here doing that. I mean, robots everywhere in the office, right? But if you think about how much data you need for robotic foundation model,
I think the amount of data any individual company can collect by themselves is just nowhere near sufficient, right? It's kind of like, you know, you're trying to build an internet by just having Reddit or just having Facebook. There are great websites, a lot of users, but it's not enough, right? So when we think about data, there has to be some sort of data acquisition happening, right? You buy data, you look at data that's already out there. And then there's many different tiers, right? You mentioned data quality. I think data quality in robotics is a non-stationary problem in the sense that what is high-quality data for your model changes over time. When your model doesn't know anything, like when it's zero, any data is useful. You can use a lot of video data. In the case of egocentric data, I think it's actually a very good way of pre-training robots because human data is so diverse. It covers every single physical activity you can possibly imagine. And that gives the robot the model of such a strong prior on how things,
how the world can evolve around a embodied actor, human. But the issue with human data is that before your robot looks exactly like a human, there's going to be some gap between human actions and the robot actions. So just by training on human data, today it's not very likely. you can just execute robot actions directly. So you still need some amount of adaptation using robots' own data, right? But the robots' own data collected on a robot is going to be much more expensive and much harder to collect. So the kind of recipe we're thinking about is like how do we take the largest source of data we have today, like egocentric data, to give the model a strong pire over everything physical manipulation can cover and then combine that with a small amount of robotics data to make the robot master whatever task we're interested in. So data quality and getting data in robotics is really, I think it's a fascinating multifaceted problem.
But the reality is that there's not a single winning strategy like, oh, here's one kind of data, I'm only going to collect on that, which will give you a strong foundation model. You really need to think about this human data covers this part of robot cognition I need. robot data covers low-level reflex dexterity the robot also needs and put them into one model. And I think that's what gives a really adaptable, really strong model at the end. I'll prompt you, just for, again, for the people listening who want to work with you, what data vendors do you want? This is your call for data. Yeah, no, that's a great question. And yeah, so in our Dyna2 blog at the end, we actually have an email address called data partnerships at diana.co. So if you're a data vendor that has a lot of high quality, let it be egocentric data, robot data, video data, or anything you think could help robots, send it to that email, our team will take a look, and it will get back to you. Yeah, but at your stage,
you're probably not buying any more egocentric data off the shelf. You probably want to be like, here's what I need. Is there a niche that's lacking? You need a scale AI, you need a core for doing this. I see. The customers that don't work in robotics are probably thinking like, okay, some niche factory, like, you know, you showed putting tubes in. There's only so much data you'll find about that, but, like, would a lot of that help you? Yeah, no, I mean, if you really want to nail a task, having data from that task will certainly help you a lot, right? So, for us, it's like, we still think, you know, just a million hours of data is not enough. It's just the beginning. We showed the first model on a million-hour scale, but we need more than that, right? So we're still looking at a lot of just raw, diverse data that we can get. But we're also thinking about how do we get more custom data, either collected in-house or by our partner, for really specific niche tasks. Because I think you still need that to get to excellence that any model needs to actually be useful in the physical world.
It's kind of like humans. you know, if Sean or me, we go work at Rosewood Hotel tomorrow, we're not going to be able to make the bed the way they want. We need a lot of training. So that kind of data, like special data, that's kind of like what Mark Corr is doing today for language model, I think will be very, very valuable for robotics as well. Yeah, so hotels, you know, strap a GoPro on your employees' heads. And then, they put themselves in there. So one thing that we discussed is the closing the scenes are real. And what's very interesting is now you can basically fabricate environments on the fly. Have you tried that with the frontier models? What's your experience? Are they good enough? Are you using any world model companies to generate these and train on them? Yeah. So I think generating synthetic environments, synthetic data, simulation data for robotics, is going to be one of the next frontiers, right? Because today, people have looked at egocentric data, robot data.
You know, those are scaling. But I think synthetic data will be a new dimension of scaling. So going back to your question, like, yeah, we have been exploring, like, using frontier models to generate synthetic environments for us on our data, on our environments that we care about. And surprisingly, I think now it's at a point where this technology which is actually very much worth going really, really deep into. So for some context, in my PhD, I primarily focused on simulation-based training for robotics. Back then, simulation wasn't ready, but we had this paper called Eureka, which was the first paper taking a large language model. At the time, it's GBD-4. We just had a self-generate environment, generate reward functions or reinforcement learning, and just do things in simulation. And at the end, I think we had this really nice demo of the robots spinning pencils. That was really cool at the time. But that kind of thing was still very, very limited at the time. Because back then, the model didn't really have good vision capability, didn't have an innate 3D understanding.
So it was basically just generating code and using very limited feedback from text to try to come up with new simulation environments. But today, the vision capability of these frontier models are crazy. They can do real-to-sim, do catting, there's 3D reconstruction, all of that. Now it's at a tipping point where this technology could really accelerate robotics. And for us, we think about that as a way to accelerate our internal progress because we're building models, we're building hardware. So if a frontier model can give us more data that way, generate really tailored data for ourselves, that's extremely useful for us. And another thing we've been thinking about is instead of using these models to generate 3D environments, we have also used our own world model, the world action model I was telling you about. Because the model not only generates action, it can also generate videos. The model can also generate its own training data. So that becomes a self-fulfilling flywheel
that I think will also be powerful. So overall, I'm just really excited about this direction because I think even though we have scaled to a million hours of data, we are deploying a bunch of robots, the world was actually you know already starting to do very cool things we're just at the beginning just the tip of iceberg for like what is there to come yeah for those on the research side we recently had runway on the podcast one of their things is robotic world models they're shifting a little towards there so you know nice people to look at it one of the questions i have about you making your own models is what is the constraints you operate in so if you draw a parallel to language models, you see like GPT-OSS-20B is very fit for your average MacBook. Then there's a larger one that's fit for a single GPU. Do you work in the constraints of robot model on device, in cloud, a hybrid? And then how does that affect your scaling law of data?
You know, a million hours is great, but like, do we just scale up parameters, data? Yeah, no, that's a great question. So I think what's really different about robots versus language model and other applications is that for coding agents, language model, it's okay if it has latency, right? Like you know today whenever I ask ChatGP it takes like a couple of seconds before it spits out anything But for robots like the inference latency has to be very very short like the robot needs to act like you can just hold a knife and not do anything for three seconds that going to freak people out right yeah we saw someone put their real hand under and our model's pretty smart so that's okay but uh in general like if you think about very dynamic tasks like for example you want your robot to like you know hold a i don't know a tennis racket and, you know, juggle the ball, right? It's very dynamic, very reactive. You can't just, like, the physics gravity doesn't wait for you, right? So for that reason, robotics model needs to be able to inference very fast. And the fastest way to do that is
by serving on-prem, like, on-device, right? Because if you call a model... Networking. There's no guarantee. There's no guarantee, right? So for that reason, the model that gets deployed eventually has to be of reasonable size that can be served locally. But that doesn't mean that the initial model you train also has to be small. Like in language model, people do distillation. The best way to make a small model very smart is by doing distillation. You're training the biggest model, then you distill. So I think in robotics, we're getting there, but I think that's what people are going to converge on. How about like inference? You have your own inference stack. A lot of this is architecture, you've pulled, diffusion, and whatnot. I'm guessing you can pull off of something. Anything you want to share? Yeah, so we build our own inference stack for whatever model we deploy because, like I was saying, latency is so important. So only the whole stack is extremely important for robotics.
You want to optimize the inference speed for the kind of model you're running, and there's a lot of work in there, so that's what we do. Yeah, you're really full stack. Like everything from like, you know, the actuators all the way to the industrial design ID, which I didn't really know as an acronym. Well, I guess to the models and data as well. I'm curious, like, are these your own actuators or are they, how much of this is your own? Like, of course, the design, you know, it's not like humanoid, but yeah. Actuators, like how far down the robotics stack? Yeah. So the way we think about what we need to own versus what we can buy is like, if the... input output and other components very, very clear, and like there's already extremely good mature solution, then there's no point to building house. For example, on this robot, you see the lidars, right? So those are black circles, those are lidars to help the robot detect obstacles, navigate surroundings. So that's a very mature technology that people
have been using for now decades. It's on self-driving car, so we don't need to build lighter from scratch right same goes with some cameras but for anything that we think is extremely crucial for the whole system's performance at the end our vision is to be able to own that and build ourselves so one thing is that you mentioned actuator so that's something we're working on and we're going to own ourselves the reason is that like the quality and how you design actually that really matters for how well you can model the robot, right? Actuator is what drives the robot. To be able to model your robot very well in simulation or to do any kind of modeling, you need to select actuators that's very good that can actually be easily modelable. So that's what we care about eventually, so we're going to own that. Same thing with the robot's proportion. This robot's proportion is like we measure it against real people. Why do we do that? Because we're pre-training on human data. That's transfer, right? So there's a lot of these kind of decisions that goes into hardware that's very much tied to,
because eventually it's hardware that carries intelligence. Intelligence is the extremely important thing. We want to make sure the hardware serves for that. I'll just highlight, I don't know if this is relevant to you, but one of the most interesting robotics discussions I've had is someone who was very stressed out about actuators and specifically magnets. Because apparently we don't make magnets in the U.S. No, we don't. and there's only two countries that make magnets? Rare earth material. Rare earth material. Rare earth material. Rare earth material. Rare earth material. Rare earth material. Yeah, right. I don't know what the, what's the chemical, what's the material. I don't know what the thing is. Yeah, yeah. So yeah, if anyone's interested in that, that's apparently a bottleneck that we have. No, you're not. No, I don't know. Yes. So what do we do? Yeah. I mean, I mean, it's a good question, right? I think there's a lot of exciting discussions on bringing manufacturing back to the US, but, you know, for robots especially, that's actually much harder than what it seems and I would say even now there isn't a company in the US that's truly
building everything from scratch in the US even when they say they assemble a robot, they build whatever they're actually doing in the US, they're still sourcing the raw materials from other places in the world and I think that's something to really be aware of as a robot builder, I think as a full stack robotic company we realize just how long the supply chain is and how long the whole problem is is actually extremely hard and I think these days a lot of discussion centers around a robot foundation model model data but I think hardware and just how hard it is to build good hardware it's very under emphasized but I think that's going to be extremely important this is a platform right actually there's some companies that choose to be let's call it platform-less, they only do the model. And you'll say, we'll deploy on any platform. We'll deploy on Optimus. Off-the-shelf robotics. It's a choice, right? Obviously, you own everything, so you can do that. Do you see yourself
building more in the US, or do you see building your own global supply chain? What's the direction that is likely? Yeah, so we are currently exploring many different options, right? Because with global supply chain, then there is some geopolitical things. Shipping. shipping, also shipping delays and all that stuff. Literally ships for robots. Yeah, and in the US it's just that going from zero to one will take some time, right? So we're trying to think about a solution that can both allow us to build more in the US while leveraging global supply chain, right? But I do think, going back to your previous question on like some companies choose to just build model, we build everything I think. I think it's very important to get this right. I feel that for robotics, the hard thing is building a whole system, or the necessary thing is to build a whole system. Previously, I was at DeepMind. I was at NVIDIA primarily just building models, and I saw the upper bound of the system when you don't control the hardware,
when you don't get to optimize that. Because if you think about the value creation for robots, eventually robots are here to deliver a service to solve some physical tasks. so if you want a self-physical task you want to be able to optimize everything and that's important i mean we have the robot you got to tell us about the design um your own custom platform what do you call this what do we call it yeah so it's not humanoid um it's very smooth but what's the what's the rotating arm yeah so we think of this as generally like a semi-humanoid so basically the upper body is you know like a humanoid it's got you know of course shoulder got arms it also got like four degrees of freedom on the waist so you can basically do all the upper body motion that a human can do but it's a semi-humanoid because the lower body is wheels all right so why do we choose wheels because i think there is a difference there is the you know optimal like practicality versus performance trade-off i think with legs the energy the energy consumption will
be a lot higher it'll be a lot more unstable you know safety will be extremely extremely hard to guarantee. So right now for Leggett Robots, there's actually no guarantee that the robot will stay upright, balanced the entire time. I'm sure you guys have seen a lot of those robot dancing videos. Like the robots. They fall over very easily. You also see the demos that you can tell in our production where you can box the robot and you can push it over and it's very good. But that robot is just good at balance. I think the more interesting thing that you guys have innovated. We have one of the prototypes, which is the Mewtwo back here. This is just like an up-down axis and you've chosen to then move towards something like this, which has the ability to lean. And we're going to show the laundry demo where you have to lean into machines. That's another degree of freedom that I don't even have the words for it. It's not pitch, it's not yaw. Yeah, yeah, yeah. So, yeah, how do we think about that?
So, actually, it's very useful exercise. I think sometimes a couple years ago when I was exercising, I accidentally pulled a muscle. I'm sure you guys have that experience. Then the next few days, you just couldn't move or you pulled it or you slept in the wrong position. So your neck is very stiff. We have all experienced that. And then whenever you experience that, you kind of realize, wow, so many muscles, so many degrees of freedom that we use in our daily life that we take for granted. but when it's disabled like it's very awkward for you to do some tasks that you feel are very natural right so that's also how we think about like when we design robots when you have like a this kind of design which is this purely elevator could only go up and down we realize a lot of the like human torso movement like we use our like you know waist back a lot for like day-to-day physical activity right even like if i want to get this bottle like i'm not just moving my arms It's actually very strange for me if I had to intentionally think about fixing my upper body.
I would always do this, right? So there's just a lot of subconscious way that humans move their body that I think will be equally useful if a robot has a deeper freedom. And if you further think about, okay, we want to learn from human data. Humans are moving their torso all the time. You want to be able to ingest that into the model to control the robot. But if you have a form factor that doesn't allow for that, then the transfer becomes less and the robot becomes less dexterous and it's just more awkward what's the data labeling side of this like i you know you've seen people um is this the last like post-training fine-tuning side of actually the hour of using the robot tele-operated or remote-controlled mapping motion or like does some of it generalize over uh when you say labeling, you mean like taking the model you have that predicts state to mapping it to your specific hardware? Oh, yeah. Yeah. It generates this very well. So for all the demos that I have shown you on the new robot, because the new robot, it got ready not so long ago.
So we quite literally did not have a lot of data compared to the stationary arms we showed you, which had much more data. But a new robot, the model has nothing that's in pre-training. in some of our pre-trained model. It's able to learn the tasks that you saw very quickly. And I credit a lot of that too. Even before the hardware is ready, we're already committed to pre-training like humans because we knew at some point our robots will be like humans. You can get ahead on the training side while hardware is getting ready. And I think now we're seeing that the transfer is actually there and is actually very helpful. Talk about the eval side of this. So you can have predictions, you can have it do stuff. And every now and then we see it. you test on very niche things as well, so like filling a pill bottle. How long does that process take? How do you think about the aspect of actually deploying on a new task, evaluating it, iterating? What does that look like? Yeah, so if we want to learn a new task, we basically do a little bit of robot data collection.
Then the model... What is a little bit? Yeah, like a couple hours, a couple hours. Yeah, we're in some of the tasks, like just tens of minutes, right? Yeah. and then the chopping one was 45 minutes yeah the open the fridge was London and that's an interview that's like an onboarding task for one of your engineers yeah yeah so fun thing if you want to work here you know find the task have the robot do it yeah pitch me a new task and I'll come to the office you know collect some data train a model and see what happens tie your shoes Julie is tying yeah that'll be cool but yeah so you know a little small amount of data collected train a model then we just deploy the model in the real world and then we look at the performance. To fill in collected means like you have a person actually operating remote control, doing the task for a bit, and then you're trained, and it does okay, you improve. How do you measure? Yeah, yeah. So when you're training the model, there's certain metrics you can look at, right? Just like I'm training a model.
It converges nicely. Now, after that, for robotics today, we just run the model in the real world, right, on the, you know, same setup that the data is collected to see how the model does. Sometimes the model just works great out of the box, right? You don't really need to do much more. But when a model's, you know, like maybe like 70%, 80% there, then you see how the model behaves. You figure out what it's not good at. Then you can, like, collect a bit more data to iterate, right? I think of this as, like, the robotics version of, like, reinforcement learning from human feedback, right? The robot rolls out, you can score it. Good, bad, somewhat good. And then that data, the robot's only experience can be used to train the model. And you can also just collect more data yourself to train a model, right? Eventually, you know, our goal is like, you know, this robot is going to be our platform. Anyone should be able to train tasks on it. I want to get a bit of a prediction and like timeline to where that goes. Right now the tasks are somewhat simple, like take laundry out.
It's a towel. You can't crush it. Chop some food. There's also the side of like, okay, set up this filming studio, right? Move stuff around, bring a table, set up lights. I think manage my data center. Yeah, yeah. Plug in stuff. And also recharge another robot. Yeah, yeah. When do we see the factory or like, what do we need to scale up? Is it model? Is it everything? It seems like your hardware is set for that. But where do we see it go to a point where I can go from, instead of just cut one thing to, you know, okay, here's a recipe, like full send. Yeah. Yeah. Yeah. I would say to get to truly general purpose robots, like basically a robot or a model that does anything. like not not not that like okay so to keep it somewhat grounded on a technical level like when do we start to see us pushing that feedback right so instead of very simple chopping yeah uh
maybe a five to ten minute sequence right yeah where now the eval step it can break at many more points instead of just a one pill bottle yeah uh 10 different pills all in a sequence right what's limiting us what are we pushing on yeah i think yeah i think a couple things one is that like the laundry demo that you have seen, yeah, it's going to be like one hour to finish the whole loop, right? So the longest duration that a robot can do like a full job is already in the hour range, right? But, you know, to be able to do that for any task, you know, I think the bottleneck is coming back to data and hardware, right? So for some of the tasks, you know, for example, setting up the space, you know, you might need more than like a, you know, the parallel jaw gripper, right? You might need something more dexterous. like a hand, like a human hand, right? But then if you want to try a model on the hand, then you're bottlenecked by the hardware stability. Like hand today, the best hands, Dexter's hands are still not durable enough. They overheat pretty quickly, right? So that becomes a bottleneck, right?
You quite literally have to put an eye back. We're not just auto-researching, make better model we have. We have hardware limitations. Yeah, so hardware limitations are big things. But then if hardware is limited, then that will slow down everything, right? Because to know that you're making progress on any task, you eventually have to eval on the hardware, right? So then without the eval being very spontaneous, very fast, that also limits your research progress, right? Because then how do we collect the right data, right? I think how do we collect the right data to do extremely complex, like setting up this studio, right? Because you can imagine, like today, most of the data is vision-based. It's like video streams and like, you know, some encoding of your hand motion where the robots are joints. But humans have a lot more sensors. You know, we hear things. We feel things. Smell. Yeah, you smell things, right? So we subconsciously used all of those to help us be so good at manipulating the physical world.
but today like if you're not capturing that at all then even when we scale to millions of hours you might just be missing critical dimensions of the task so you'll never be able to solve a task right so I think those are like what I consider like you know what's dragging out the timeline but for tasks or for workflows that you can collect data today to high fidelity then I don't necessarily think there's a fundamental bottleneck right just like what we are demonstrating to the public this week. We have a physical agent that can do the entire laundry workflow as a human would. Because for that task, we don't really have like, oh you actually need more than a parallel jogger but you actually need some sensing modality that just not available today So I do think the biggest bottleneck to have a much more general thing is still hardware and data I'll take this chance to let you brag about your customers and partners. You have some announced relationships.
We can start with Best Western and then maybe some of the others that you're proud of. Cool stories, anything like that. Yeah, so we have a deployment blog post on our website that goes into much more detail. I really recommend watching the video because I think the video is... Which one, the Best Western one? No, we have like one video for all the customers we're working with. It's a really, really nice video. It shows what we're doing. And yeah, I think it's great. But yeah, we have customers, you know, Best Western, that's in the hotel space. We've put a lot of laundry, like, you know, towels for them. every hotel needs it every gym needs it every fitness center needs it what's the deployment so far? how like where can I go to which best person do I go to to see it? yeah so if you want to go somewhere I actually recommend going to our other deployment Dinh Taifung have you guys been to it? yes yes yeah you know the best very thin rappers yeah very we should have filmed there yeah we should have just filmed there a b-roll yeah but in Dinh Taifung like if you go to Dinh Taifung
or other like you know somewhat upscale restaurant, there's napkins on your table, right? So our robots today fold thousands of napkins for many, many different locations, many different dent-type phone locations in the United States. So that's actually our biggest scaled customer, right? So I want to make a distinction here. Today, there's a lot of robotics companies that's talking about deployments, talking about pilots, but what's really hard is not putting a robot in one location or doing a pilot. What's really hard is that the customers believe or validate that your robot creates enough value that they want to deploy your robots across many of their sites. So that's what happened for us with Dintai Phone, which, to the best of my knowledge, hasn't really happened for other companies doing similar like general purpose robots. So at Dintai Phone, our robots fold thousands of napkins per day. The quality standard is extremely high, because they want like, okay, the second forward seam of the napkin
is only like a couple centimeters below the, I don't even know how you call it, the pocket. So you can stick the chopsticks in. So it's actually very fine-grained, high-precision. I can show you. At some level, that's what robots are good for too, right? Humans are not the most consistent, especially in small details, whereas a robot can somewhat do it perfectly. It's interesting that's the example you bring for general-purpose robotics versus at some level, I think people would assume, you can have a specialized robot that will fold napkins perfectly to the exact millimeter as opposed to something like this. Yeah, I'm sure maybe you can, right? But the hard thing about manipulating deformable objects, right? Napkins, towels, everything is deformable. There's just infinitely many possible configurations. So that's really hard for a specialized robot, right? And what we find is that by developing a general purpose model on a robot and adapting it to these use cases, you can actually get to the production quality faster.
And what's really nice is that now that Dintai Phone has scaled, has signed a much bigger contract with us, they not only want our robots to fold napkins, now they want our robots, you know, like cut. You know, that's why we have the example, to cut food. Is that actually the second use case? That's one of the use cases, I think. Oh, wow. I mean, Dintai Phone needs to cut so many vegetables per day. they need to do the dumplings exactly to the fold that's the final boss that's the final uh i think you can i think you have the dexterity and precision to do this yeah you have a little pull ball but like you know don't break the dumplings yeah yeah i mean that's that's the obvious benefit is you can adapt them anymore i think the other thing you really touch on is the speed right yeah to make a custom napkin folding with the exact ply whatever yeah you have to make the machine you can't just amazon this yeah but this can do it pretty fast Yeah, this can do it very fast. And now it's actually a human parity. Yeah, you know, and this robot doesn't get tired, doesn't need to, you know. And I think I really like the fact that you mentioned consistency, right?
Like one issue with Dintai Phong is like, you know, they're an only location with New York location, Seattle location. They fold napkin slightly differently. But from their perspective, they want consistency. But, you know, that's exactly what these models are good at, Because models are, you know, just, it's a set of weights. You can just, like, put the weights in the different robots across the information. You can OTA update them as well. Yeah, you can just update all of them at once. You know, it just, once it works, I think it's truly, like, incredible. Final boss is Cheesecake Factory. If you know the story there, they're from scratch. Everything is very consistent down to the measured gram. Every sauce is made. Like, anywhere you go in the world, you'll have the exact same thing. If you don't know, you don't know. But, you know, that's the thing. The term that comes to mind is sort of like bitter lesson for robotics. Instead of the specialized robots, which is a lot of industrial engineering, you build a generalized platform that can do a last mile fine tuning and do all those things. Give the expert add-on outside of your, what is more bitter lesson robotics?
Yeah, I think there's several bitter lessons for robotics. One is that robotics is going to scale just like any other domains that machine learning has solved, right? So what does that mean? That means have as much data as possible. But in robotics, one thing that's a lot harder is like, what is the right data is much harder to figure out than other domains, right? In language, it's text. In video games, it's video game data. But for robotics, like what sensors you choose to determine what kind of data you have, right? But if you have the right set of sensors and just scale that data, I think you'll get predictable return on model performance. So in that way, robotics isn't so different. So that's the better lesson. As a core worry of that is that, like, there's a lot of research in robotics that's coming out with very specific priors. Like, for example, we need to make the robots see objects as they are, draw some boxes. That will give robots better perception, right?
But I think the better lesson here is that just keep the algorithm simpler and scale the right kind of data. then generalization, better behavior will emerge. So that's not so different. And the second, I think that's the main better lesson, which is like at the end of the day, scaling will work. But in robotics, to scale and how to scale is just much harder because there is no internet. You have to come up with your hardware, come up with the sensors, get all of those right, and then scale. I mean, there's the argument that the world is very made for humans. It should be a human, right? As hard of a hardware problem that is, think 10, 20, 100, 200 years down the line, can we make a really efficient human? But you have to be practical is what we have now, right? Yeah. Yeah. So the way I think about it is like, yes, eventually the robot should, if you want to build a general purpose robot, right, like a machine that can be adapted to as many use cases as possible. I think human form factor will be the best one
just because that's what we have been doing for ages, right? But I think the best way to actually build a human robot is to take an iterative approach. Because robotics is so hard, the whole problem, the whole stack is so long, it's really hard to know a priori what's the right decision to make, right? And because hardware decision is much more expensive and much more costly, just because hardware iteration is a lot slower, you actually want to take an incremental iterative approach, not going all the way to the final form factor because the chances that the thing you build actually doesn't last, it's not good enough. So you just end up scratching it anyway. It's public news. Optimus has already gone through many, many iterations and they had to scratch their designs. And I think by iterating with a semi-humanoid form factor and actually putting them out to real customers or getting models redeployed, you get that feedback loop that you wouldn't get if you're just trying to build a warehouse, humanoid, and you spend like five, ten years building it.
I think the iterative approach will actually get us closer to the final robot faster. And I will say, you know, for those listening and not watching, it's probably the smoothest robot we've seen. Every humanoid you've seen is jerky, and even humans don't walk as smooth as this robot. Because, yeah, the model can move every single motor at once. you're more than two cohorts and that's actually a very hard problem because if you think about the model is outputting action, there's the action dimension, right? The bigger the dimension is, the harder to fit the model to the data, but here the action space is quite large we did a very good job to make sure the model fits well and gives you a smooth... Can you bound the order of magnitude of the action space or is that... Yeah, so it's in the orders of like you know, about a hundred action dimensions. And these are all continuous, right? Continuous, right. So the model is basically predicting at very high frequency, you know, like at least 50 dimensional vector
like 10, 20 times a second to get that continuous motion. And potentially predicting 1 to 2 seconds out so that is another 100 frames or whatever. There's a bit of a history similar to context of previous state, I guess. So context is a very important thing about it, right? Because otherwise, if you're just making a decision based on the current observation, sometimes it's really hard to tell what to do next, right? For example, if you think about opening a microwave, in the middle part, it's unclear whether or not you're a poser or trying to open it, right? So context is also really important. Yeah. And I have a screenshot of the Fridge demo where there's agentic planning and tool hauling and all those things. So we can show that for listeners. I think that's an interesting side after the model. Yeah. How do you wrap it around into agentic harness? Like what is cloud deployment, cloud code a UI? You have a lot of cool UIs. Yeah. But, you know, what goes into wrapping model output towards final thing?
Is this custom per use case? Is it you have your own SDK? Yeah, yeah. So, I mean, eventually we will have our own SDK. But the way we think about it is we want a general harness layer for robotics foundation model. Today, that is our own model. The way I think about it is for any real task, long task in the physical world, there is a lot of high-level decision-making you have to do. It's not just like robot only reasoning about the physical world in the action, continuous trajectories, because that's a very low-level, the thing you actually execute in the physical world. But that's not the intent that, you know, like when we are doing decision making, we think about steps of a recipe. We think about, oh, like I finished this, I need to do that. While I'm waiting for this part to finish, I need to go somewhere else to do something. There's a lot of high-level cognition, decision making that's happening. And I think for robots to handle, even, you know, the laundry task we're showing you, it has to have that capability because, you know, it needs to reason,
okay, the washer is running, so I should go do something else while the washer is finishing. But now the washer is done, I should take the towels from the washer and put it in dryer immediately, right? Because if not, then that becomes a bottleneck in the whole workflow, right? So there's a lot of reasoning that needs to happen for robotics. And I think in theory, you could just try to learn that with a low-level model that's outputting actions, but it would be extremely inefficient. So that is having a hierarchical system, like putting a harness, like an agentic system around our world action model is what allow the model to compose different capabilities, different skills to solve a much longer horizon task. It's very much like in language model, right? Like two years ago, three years ago, the model was only good at autocomplete. Like humans have to like tap, tap, tap to get the model to keep spitting out code. But today just like an agentic system just carries the end-to-end task. And I think that's important because I think today in robotics, people are still thinking about autonomy
at the very task level, like one minute, 30 second task. But really the value is about tasks or like workflows that go on like unsupervised for hours. And that's what we're building towards. And that's why I think thinking about the robotics problem, not just as a modeling problem, but rather as a system problem, you need good agent, good harness engineer, good model, good hardware, everything. It's like how we think general purpose robots ought to be solved. Do you guys see benefits from language model coding tools getting better? So new Opus 5.5, new Astra. Do you have language models in your agent harness? How does AGI being developed in language model space affect you guys? No, no. Yeah, no, absolutely. Like it affects us very deeply in many ways. One is that like we're extremely AI native company. Right. Like coding agents, all of that is a very fundamental part of our work.
And we're very welcoming of that. Like whenever there's a new model, we're the first one to test it, right? Like when GBD6 came out, we had like a company-wide hackathon the same week. And the thing that our engineers built was incredible. And many of them are, many of the features we built is already in production, right? So we really like using coding agents to accelerate our work. Just for the people interested, anything surprising in GPT-6 that you found? Yeah, I think it's about the ability for it to construct virtual environments. Right, turns from... I got it. ...dissimilation. We talked about that 20 minutes ago. I think that's really exciting. It's interesting. There were so many CAD, Zillow to 3D-ish. He lost the hackathon to a CAD... I did the CAD bullshit. Other way, other way. No, oh. that was i wanted gp2 hackathon just for fun i was like i know nothing can yeah um might as well play around with it because every demo is doing it i'm like it's gonna be garbage
i'm like what's kind of grounded it's kind of good but it's just hackathon stuff yeah um cool i i was going to round out uh some of the use cases and then go into a little bit of company culture and your personal background yeah i have two uh two technical questions yeah uh one is are there any like goals you want to set for yourself like six months one year two year timeline that you see robots should be able to do fill in the blank that you're kind of working towards yeah i mean in the six months to one year friend our goal is definitely like scaling up our robots and our model and truly getting them to deploy it i mean like a task like uh right now it's cutting or opening a fridge, is there, like, do you set yourself to by this timeline we should, to stay on track, be able to do whatever? Yeah, I think in terms of deployments, we're exploring many different industries. There isn't a particular task we think we have to nail, right? Because our goal is to build a general model, a general platform.
And we think of each different task as like validation of our platform as a way, as a wedge for us to figure out how to build everything better. So today we're doing a lot of that in laundry, in restaurants. We have already deployed tens of robots, but our goal next year is that overall just deploying hundreds of robots. My part two on the last technical question is, how do you see the rest of the industry? So fill in for people. What other approaches are people taking to world models? Why are they wrong? What is different but good about their approaches as well? So just what is the landscape of robotic world models in this space, and how have you come to your current? Yeah, that's a great question. So I think robotics is the most exciting space today, and there are just so many amazing companies that I truly respect. They've been doing great frontier work like us, and it's very exciting. And I think what we are seeing today is that there are still many different approaches to robotics.
We believe that hardware needs to be built in-house. We need to own the whole chain. We believe that scaling human data is extremely important. But there are companies that's betting on just scaling robots' data or scaling some sort of intermediate data collection devices. All of them are in play, and I think it's different approaches. We'll just see what happens. I think right now it's still a bit early to tell, but we feel pretty good about the way we're building things just because we as a company, culture-wise, mission-wise, we're not here to just build a model. We're here to truly get robots to deploy. So we deploy as much as possible, work on the hard problems, so we identify problems much earlier on. So then I think that really helps us identify what is the true bottleneck and then solve it. And I think for folks, for people who are only working on one part of the problem, it's kind of like fog of war. You don't really see the whole picture, and you might be building something that's extremely cool technologically, but may not be what people need or want at the end.
I think there's a whole graveyard of robotics company and I think all of them had very shiny very cool robots but just figuring out what people actually want is actually very easy to say you know like build something people want You know, everyone says that, but it's actually really hard to execute about this company. On the technical side, you have your world action model. Is that standard across industry? Is there other directions people are taking? Yeah, I would say that's also not standard. So we're building world action model on top of world model. So there's many companies building world models. You mentioned Runway. They're also getting to adapt video world models. There are also companies building vision language action models. Really? So that's like taking vision language models and adapting them to robotics. So I think there's many different ways to go about it. But I think at the end of the day, what we call the models is less important than what we believe the model needs to be able to do at a first principle level.
So I want to explain that a bit. I think for robotics, the most important thing is that you need to be able to predict the future. Right. But robotics, any physical system is fundamentally about based on the information you have at the present moment and before, what should you do next? So it's really about predicting what comes next. So predicting robot actions, like predicting what the robot should do next. But if you think about it, robot is just a part of the world. Right. Robot influences the world, but the world also influences how the robot should behave in that environment. So if you think about it this way, then the most first principle thing you can do is just predict as much of the world that you can possibly predict. So that's why we believe predicting the future is extremely important. And today, the instantiation is the world action model. And VLA only predicts robot actions where some more abstract representation of the world. but whenever you're predicting abstract representation of the world
you're encoding your own bias into what's important to predict and the bitter lesson tells you let's remove human biases let's just take the most raw representation the camera input and just predict all of that right so that's how I think about modeling for robotics today so just to press you a little bit on this you're basically saying your approach is better than the VLA right because you're you're you're emphasizing prediction i fully buy that i like you sold me on it yeah if you were wrong what is the most likely number two someone else is doing interesting question yeah so yeah there's a caveat in what i've said before and i think that's where i could be wrong right well i said that you need to predict the world as much as possible right but what that doesn't say is that does your sensor have everything about the world that you need to predict? I think I touched on this a little bit, right? Like, if you're trying a world model that's purely based on
videos, I think you'll be a very powerful world model. But it may not be a sufficiently rich enough world model because you're missing critical aspects of the world, like sound, like touch, right? So I think where we could be wrong is like, okay, I have the best world model on vision, vision-based world model. But tomorrow, someone else comes out with a vision plus tactile world model that's just like 100x more data efficient just because vision is a very high information or a highly redundant input because every other pixel, they don't change that much. You can understand the world without perfect vision. But tactile, other modality might be much denser information. So maybe having that, predicting that, will just allow you to use much less vision. So you can get to the same performance with much less compute, with much less data. Right. I think you will be able to adapt very easily. No, exactly.
There's also a level of how much data... Right. So the reason why I bring this up is because I think if a vision tactile world model or a vision tactile audio, whatever world model, is the final thing that solves robotics, and I think robotics companies will be able to do that better than video generation companies is trying to pivot to robotics the reason is like to understand sensing it's actually very complicated like we've been building that since the company started so we know the bottleneck we know how to combine them but for if you're just trying to adapt the video model to robotics action then like you know if we were wrong if you know video model is not enough then like you don't really have the know-how to get tactile to work very well. So we have that. This is a side question, but I think it's a quick one. Heat seems very important. Is infrared just another color to you, or is that... Yeah, it could be another color, another input to the model. It could be in the cooking scenario, actually.
Like I know companies that's using infrared to know how cooked food is, because that's really hard to tell from RGB camera, right? My very naive pushback on your last point is maybe we don't need to understand hardware, cloud code, or codex can just, you know, pipe code it in. There's a lot you can do without understanding, but of course... It's just not in the distribution. So I wanted to bring it a little bit to your personal story or your background. We both went to Penn. I did not... I just found out today. Yes. My big regret is I didn't join the Docker Challenge, which then I could have been, like, early Waymo or something. you were at Grasp, and then you've also worked at Google and NVIDIA. What are the different focuses of, let's say, academia versus Google versus NVIDIA? You've seen all these places, right? And then that obviously caused you to say, like, screw all that, I'm going to do my own thing, right? You could have joined OpenAI's robotics. Yeah.
So maybe just take us through chronologically, but also one thing you learned from each. Yeah, so chronologically, yeah, maybe it's useful to talk about how I got into AI in the beginning, right? so as a kid so I spent time in Japan and China I grew up playing Go you know going AlphaGo so when AlphaGo came out I was a senior in high school and I was mind blown because I've been playing this game for many many years it's so complicated I think before AlphaGo came out people were like okay Go is one of the games that AI will never solve the search space is like larger than the total number of atoms in the world how could you possibly search for solutions in that then like you know RL reinforcement learning just like cracked it. And I think that was how I got into AI initially. I was just really interested in like models or systems, agents that can self-improve. So when I got to Penn as a PhD student, I just really wanted to work on reinforcement learning. So I'm co-advised. Both my advisors were interested in RL at the time.
One of my advisors was more in robotics. He did a postdoc at Berkeley Robotics Act. So that's how I got into robots. at Penn. We have Grassblatt, I think one of the best places to do robotics. And so that's how I got into doing RL for robotics in my PhD. And then I did a bunch of research thinking about how to connect reinforcement learning with human data, how to do reinforcement learning theory in a very rigorous way. And then I went to NVIDIA. That's when GPT-4 came out. at the time we were very interested in just solving pen spinning tasks I don't know why like it's the dexterity limit I mean I think you can solve Rubik's Cube at the time I was working with Jim Fenn and Yuko which you guys probably also know like yeah we were just like okay let's try to do dexterous pen spinning the initial idea was like learning from human videos right we were trying to watch humans do it but then I realized okay today
we don't have a dexterous hand that can spin pens at all. So how would I even be able to evaluate the algorithm, even if learning from human worked at all? So I said, okay, we need to first try this in simulation. Then as soon as I tried to set up a simulated environment for a robot hand with a pen, I immediately saw what the issue is. The issue is, like, if I had to come up with this simulation environment, the reward function for reinforcement learning to solve pen spinning, that's impossible. Like, I wouldn't be able to come up with all the terms that you need to get RL to learn the right behavior. And then I was just thinking, what if a model that can write code can do that? That's what became the Eureka project, right? We basically, in my opinion, we had the first recursive self-improving robotic agent in simulation, because we really used that to solve a new task that no one has demonstrated before. And that allowed me to see the potential of using language models, using coding models to really accelerate
robotics. So then I went to Google DeepMind, because at the time, I mean, even today, they have one of the frontier models in Gemini, right? So I was looking at how to use Gemini for robotics. But eventually I realized, like, I had a lot of fun doing academic research, but there was always a question in the back of my mind, like, does any of this matter? You know, like, when you're working on this kind of thing in the lab, like, you know, you asked me, how do we come up with so many interesting, fun tasks. You're basically doing your own eval. You're grading your own homework. I wanted something more real. I wanted something that could actually be used by millions of people in the world. And I felt 2024 was when we started Dynum, like end of 2024. That was the right time that we can take some of these technology to actually putting them out in the real world. So that's why I started Dynum with Linden, New York. And fast forward two years, we built our platform, our model, Our robots are in Tsing Tsai Phong. Go check it out. Go eat. Yeah, go eat.
It's been a journey. But what still gets me really excited is, you know, like a lot of ideas that I temporarily abandoned when we started Dynum because, you know, to build a company, you have to be very practical. Like I think simulation wasn't ready in 2024. But now with, you know, like the new frontier models and what we're seeing internally, like this might change. And that's very exciting. yeah and uh so then also let's talk about company culture yeah um what principles you're you're building with the company with obviously like the the you're responsible for the science yeah and the research agenda uh and it just seems like when we meet the engineers they're they're very engaged and they have a lot of ownership they have a lot of motivations i'll say it's it's interesting to see how many side projects people just work on so some of the demos we've seen it's It's just the engineers that work on it were like, yeah, this seems fun. Might as well do it. To your point on fun evals right here, like two feet behind the camera. Can't talk about that. No, I mean, the thing is, the eval is just there's highlighters,
four highlighters being rubber banded together. It's like who comes up with, ah, yes, we need to test putting rubber bands on highlighters. Fun stuff. People are very creative here. It's a beautiful space. Yeah, I think culture. Yeah, so let's first talk about how we run the company, right? We think of ourselves as eventually like a research plus product company. It's kind of an open ad where you do frontier research, but eventually all of them make their way into Codex to chat GPT. That's how we think about it. We're not here to just do open-ended, like whatever thing that interests us at the time. We're always product-driven. We want to deploy our robots, our platform to a new customer. What are the technical problems we have to solve, right? We have to solve generalization. We have to solve whole body control. We have to solve how to adapt quickly. We have to solve how to make the robot follow language. We have to solve dexterity. So once all those problems are very clear, then like, I mean, our engineers are very capable.
They're very smart. So they just create instances of the task. They create tasks that would stress test those capabilities, right? like the grabbing and drink task is just how we test language following right you can just specify what you want if the model follows intent follows instruction you should be able to do it so that's how we think about like at the top level we identify what are the things we have to solve then we have a lot of bottom sub project to like actually drive execution to solve them and you know you hire the right people and everyone here is super passionate about robots you know they've been doing this for a long time they love it and we just create a culture where it just naturally happens and it's a really fun place to work. What's the split between technical research software versus hardware side of a company? Yeah, we recently grew so much, so I don't have the perfect number, but I would say on the hardware side, we have probably 30%, 40% of hardware just because hardware, you need a lot more people.
And then we have around 10 people working on models Then we have software engineers, robotics engineers. We have a lot of very talented people on the business side. The most fun thing about building a robotics company is you see everything. Everything under this fund that could possibly be helpful will be helpful. So you just get so much exposure working with so many different people from many different backgrounds. We're all very passionate about robots. And I think it's just been really eye-opening for me as a founder because when I was a researcher at a lab or like a PhD student, I was talking to researchers every day, and that was great. That was really good. I still get to do that every day, but now I also get to learn just from so many different people from different walks of life. Some of our people who collect data, they had no robotics experience. They were working in retail, working in some other jobs, and they came here. They also became very well-trained in robotics, And I think this is pretty amazing to see.
And I think of myself as like I'm still learning, you know. I think of myself as just always learning in the robotics space. And I haven't learned so much as I am now. You know, even though, you know, you think about me now, I'm not a student anymore. I'm here like running a company, managing a lot of things. But I still feel like the day-to-day learning is like just so much. And then just to close off, where is Dinah going? two years, five years, what's the vision? Yeah, I think our vision is to truly, the high-level mission is truly bring robots and intelligence into the physical world. That means actually seeing our robots deployed, thousands of customers, even more millions of robots, that's where we want to get to. What's the name from? Dyna? Dynamic? Is there a story? Yeah, there's many stories. So I named Dinah.
There was a lot of... Take the credit. Internal different options. But how the name came to be was... There are two things. One is that... So Touring Award winner Richard Sutton was like the pioneer reinforcement runner. He wrote a paper called Dinah many, many, many years ago. It's about basically an agent that self-improves in a world model. And I felt even when we started the company, Like, we weren't doing world model yet, but I felt that's how robotics will get solved. And now our, you know, technology, technology directions that converging to that. So I felt that was a really neat inspiration. Also, because I've worked in reinforcement, I only have a lot of respect for Richard. The second thing is that it's a bit more personal. Like, I grew up in Japan and, you know, the year I was born, there was just like a cartoon show. I don't know if you guys have seen like Ultraman. Of course. Yeah, the Ultraman.io was called Dina. Oh, yeah. So, yeah, it's a very subtle thing that people know, but I guess now everyone would.
The team is finding out too. Yeah. But I think Richard would appreciate it. I don't know if you ever talked to him. No, I've seen him at RL conferences. You should just be like, hey, this company is inspired by you. Everyone knows Richard for Bitter Lesson, but you know. Yeah, also Bitter Lesson. Yeah. Okay, any parting thoughts or calls to action? Calls to action. Yeah, I think, I do feel like as an industry, robotics is still very demo-oriented. Like I have done a lot of demos in the past, in the lab, you know, even here, like we had to show some demos. But I think we need more people that's truly mission-focused on doing whatever it takes to get robots deployed, get robotic foundation models truly integrated with hardware and seeing them at real customer sites. I think we're a pioneer in this regard and I want to see more in this field. And for the audience that's watching, if this mission inspires you, solving the hardest problems today is what makes you wake up every day and you want to contribute.
We're always hiring and we're looking forward to that. But I think just... Bay Area, anywhere else? Yes, just Bay Area today. But as company grows, never say never to other locations. Yeah, but that's what I want to say. And I wanted to see more robots in the world. Yeah, cool. Congrats on everything. I mean this is this is incredible progress for two years thank you yeah yeah I really appreciate it thank you for visiting us I hope you know it's it's been fun and that so yeah I would say like yeah I don't regret doing this on site like okay yeah we do a lot of in our studio yeah like this was worth it yeah yeah I think for robotics gotta do it on site for people listening and you know watch the watch the video version we have fun b-roll yeah
番組の概要欄(原文)
Watch along AIE NYC and join us at AIE CODE in SF next month! This episode includes a live demo of the Taku robot that is best enjoyed on YouTube. Last month, Dyna made waves by announcing Dyna-2, a world-action model pre-trained on one million hours of human video, claiming several new scaling laws on human data across four orders of magnitude. They have now followed up the model with a physical robot agent, Dyna-2.1, that has to be seen to be believed: In his talk at AIE this year, Jason talked about how the real challenge for robotics in the real world is reliable, long-horizon autonomy, and how Dyna got its models to a 99.4% success rate folding restaurant napkins for 24 hours straight, including recovering after it pulled over the whole stack. From training a world-action model on over one million hours of human video to deploying robots that fold thousands of napkins daily at Din Tai Fung, Dyna Robotics is pushing physical AI beyond impressive demos and into real-world production. In this episode, Dyna Robotics co-founder and Chief Scientist Jason Ma joins swyx on-site to unpack how robots can learn new tasks from as little as 45 minutes of demonstrations, why predicting the future of the physical world may be the key to general-purpose robotics, and what it actually takes to build robots that work reliably for real customers. We go deep on Dyna-2, Dyna’s million-hour world-action model that combines future video prediction with robot actions, the scaling laws behind human-to-robot transfer, diffusion transformers and flow matching, and why synthetic environments and self-generated training data could unlock the next wave of robotics progress. Jason also explains why Dyna builds its own hardware instead of relying on off-the-shelf humanoids, how agentic harnesses enable robots to execute hour-long workflows, why dexterous hands and missing sensory data remain major bottlenecks, and what separates real commercial deployments from the graveyard of robotics startups. We also cover world-action models versus vision-language-action models, GPT-6 and coding agents in robotics, and Jason’s journey from AlphaGo and Penn to NVIDIA, Google DeepMind, and founding Dyna. We discuss: * Why Dyna-2 was trained on over one million hours of human video * World-action models: predicting future video to guide physical robot actions * Diffusion transformers, flow matching, and real-time robotic control * How robots learn new tasks with as little as 45 minutes of demonstrations * Why robotics has no equivalent of the internet and data remains its biggest scaling challenge * Human egocentric video, robot demonstrations, and cross-embodiment transfer * Synthetic environments, simulation, and models that generate their own training data * Why robots need on-device inference, model distillation, and custom hardware * Why Dyna chose wheeled semi-humanoids instead of traditional bipedal robots * The hardware bottleneck: why dexterous robot hands still overheat * Best Western, Din Tai Fung, and the difference between robotics pilots and scaled deployments * The Bitter Lesson of Robotics: scaling data instead of engineering specialized solutions * Agentic harnesses and robots executing multi-step, hour-long physical workflows * GPT-6, coding agents, and AI-generated simulation environments for robotics research * World-action models vs. VLAs, and why vision alone may not be enough * Jason’s journey through AlphaGo, Penn, NVIDIA, Google DeepMind, and the Eureka project * Dyna’s research culture, deployment-first philosophy, and vision for millions of robots Jason Ma * LinkedIn: https://www.linkedin.com/in/jason-ma-742224a2/ * X: https://x.com/JasonMa2020 Dyna Robotics * Website: https://www.dyna.co/ * X: https://x.com/DynaRobotics Timestamps 00:00:00 Introduction and Dyna-2’s World-Action Model 00:03:08 Diffusion Transformers, Flow Matching, and Generalist Robots 00:08:19 The Robotics Data Bottleneck 00:13:50 Synthetic Data and Self-Improving World Models 00:16:51 Real-Time Inference and Model Distillation 00:19:45 Full-Stack Robotics: Hardware and Supply Chains 00:25:02 Why Dyna Built a Wheeled Semi-Humanoid 00:29:35 Teaching Robots New Tasks and Evaluating Performance 00:31:59 Autonomous Workflows and Hardware Limitations 00:36:06 Real-World Deployments at Best Western and Din Tai Fung 00:41:07 The Bitter Lesson of Robotics 00:46:13 Agentic Harnesses for Physical AI 00:49:07 GPT-6, Coding Agents, and AI-Native Robotics 00:52:02 World-Action Models vs. VLAs 00:59:17 From AlphaGo to Founding Dyna Robotics 01:04:20 Dyna’s Research Culture and the Future of Robotics Transcript Introduction: Jason Ma and Dyna Robotics Swyx [00:00:00]: All right, we’re here on site with Jason Ma, the co-founder, chief scientist of Dyna Robotics. Thanks for having us in your office. Jason Ma [00:00:06]: Of course. Thank you for coming. Vibhu [00:00:07]: It’s been a blast. We got to see—you’ll see plenty of B-roll—drinks being pulled, a lot of evals, robots with knives for the first time. So under the hood of all this you have a world action model. What is that? Dyna-2: A World Action Model That Predicts the Future Jason Ma [00:00:22]: So last month, we released our world action model called Dyna-2. So it’s the first world action model trained on more than one million hours of data. So going back to your question first, world action model is a model that’s able to predict the future video, the future state of the world, so hence the name world model. But in addition, you can also use that future generation to also produce actions robots can execute in the physical world to control the robot. So why do we do that? It’s a very powerful architecture, because if you think about how humans act in the physical world, in our brain, we are implicitly thinking about how the world will evolve based on our actions. So now we have a model architecture that’s able to do that to guide robot actions. So what we find is that by doing so, the model is much more dexterous, much more robust, and much more capable of generalizing to environments, to scenarios it’s never seen before. World Action Models: Inputs, Outputs, and Visual Reasoning Vibhu [00:01:17]: I wanna prompt this question a bit. I think a lot of people hear world model, and they think you’re outputting video or world or 3D state. You’re also doing action. I think most people don’t understand what models are under the hood of robotics. So what are the inputs and outputs? What’s the training data? What is the architecture? Give us all the details. Jason Ma [00:01:39]: So, for inputs, the most important input is video, right? You can think about videos that the robot is capturing with its cameras, right? So video or images of the past many seconds, that’s the input. But for robots, what’s really interesting is that robot also has a lot of actuators and joint encoders on itself. So the robot also knows, the angles of its joints. So those can also be inputs to this world model. That’s something that’s very different from just a pure video model that’s only looking at videos, right? So that’s the input. And additionally, for robots, you want to be able to talk to it, to instruct it to do different tasks, right? So you can also feed it language instruction. So those are what I consider the basic set of inputs that go into any robotics models, including world action models. And once we have that the output, at the basic level, it needs to output actions the robots can execute on the hardware. But in the case of world action model, what’s really interesting is that in addition to the actions, it can also output future video, right? So basically, you can almost output the future video or some representation of it first, and then use that to guide robot actions. So the way I think about it is this is kind of analogous to chain of thought, you know. And basically, the models are reasoning in the visual, the physics space, and then outputting actions. So that’s the key difference between world action models outputs versus other kind of models, robot models outputs. Diffusion Transformers, Flow Matching, and Smooth Actions Vibhu [00:03:08]: You put out a good blog post around your model. I think a lot of people understand language models or transformers, next-token predictors. In this case, you shared quite a bit. There’s diffusion, flow matching, you’re predicting next world state plus action. One thing you say is a million hours. How do you determine the architecture? Like, what are the choices there? What is the architecture? I feel like in language models, there’s a lot of take something off the shelf- Take trillions of tokens, do prediction, SFT, RL, and you have a model. What about this? How do you go from nothing to your model? Is there vanilla architecture off the shelf? Do you determine all this and what’s, what is the current state? Jason Ma [00:03:49]: Yeah, I think, yeah. So the mental framework to think about how do we build models for robotics is that there are essentially a couple things to look at. One is data, and the second is how do we make a model learn as much as possible from that data? So let’s first talk about the model actually, right? So the blog post we released is our Dyna-2 world action model. So under the hood is a diffusion transformer. The model uses an encoder-only transformer architecture. Vibhu [00:04:20]: Right, yeah. Jason Ma [00:04:20]: But what’s really interesting is that in visual domains, right, if you think about generating images, generating videos, and in this case, robots looking at images to generate actions, people have found the diffusion kind of architecture to work really well. So what is a diffusion model? A diffusion model is a model that takes some random noise and through iterative computation can go from noise to something that’s really high-dimensional, that’s something really highly defined and have very fine-grained feature. If you think about generating images, right, you want sharp edges, sharp corners, color contrast. And for robotics, even though you’re not generating image, you’re generating actions that needs to be very precise, very smooth, right? So it has kind of the same kind of consideration and desiderata as generating image. So that’s why from first principles, the whole field, not just us, have been using this kind of diffusion transformer architecture to train robotics foundation models. You need the transformer aspect because transformer is the thing that can just ingest the most amount of data, can learn. Then diffusion helps you to refine the outcome to get to the smooth, precise, fine-grained motion you need to actually execute on the robot. So that’s the architecture that goes behind a lot of our recent breakthroughs. Swyx [00:05:37]: And we’ve covered flow matching before on the podcast. It is mostly an efficiency speed-up. Like, let’s say you normally would take forty to a hundred diffusion steps. You can reduce it to four. Jason Ma [00:05:48]: Yeah, that’s right. So with the diffusion model, one thing that’s very hard in practice is that you need to tune the scheduler, like by how much you’re tuning or converting the initial noise input into the final output. So flow matching is kind of like a special case of diffusion that makes the transformation much simpler. In practice, you don’t have to tune as much, and it works just as well. That is why I think about two to three years ago, most generative modeling for image and video has shifted from a diffusion model to a flow matching model. But the concept is the same, and flow matching is just a special, simpler to tune, variant of diffusion. Yeah. Swyx [00:06:26]: It actually makes me think that. So flow matching obviously has trade-offs in quality. But actually, it’s very suited for action diffusion and robotics because you get to reevaluate in real time. Whereas in images, you are— it’s basically one shot. Jason Ma [00:06:40]: That’s right. Pretraining a Generalist Robot and Adapting to New Tasks Vibhu [00:06:41]: Which is pretty fun. We got to mess with the laundry folding robot … throw a random towel in. The models adapt, right? I think one key thing about your models is that they’re tr— they’re made to be generalists, so one foundation model and you adapt them a lot. How does that work? Basically, in 45 minutes of mapped data, you can generalize towards. We saw an example of pulling drinks out of a fridge. What’s the what’s the mindset there of one general model, and then how do you adapt to different tasks? Jason Ma [00:07:14]: So the way we think about it is that for robotics, we need to build a very general, strong base model, right? And then— Because if you think about how a human interacts and behaves in the physical world, right, we have very strong base knowledge. We can just readily do a lot of tasks. But if you want to become an expert at any given task, there is some amount of training that needs to happen. And I think to train a general-purpose robot like the one we’re building here, the same principle has to apply. So our approach is to first train a general model that’s training on as much data as we can find. So that is why in our Dyna-2 report, our model is trained over a million hours of human data as a starting point. And then given that strong foundation, what we found is we can quickly make the robot or make the model do many different tasks with a very minimal amount of fine-tuning to just tell the model, “Here’s the task I want it to do, and here’s very few amount of demonstrations,” and the model can readily do bunch of the tasks that you have seen in office. Yeah. A Million Hours of Data: Egocentric Video and Robot Demonstrations Swyx [00:08:19]: We actually have quite a few people who deal in data, who sell data. What is good data? What is bad data? What do you want to buy? I think that these are all open questions. Like, obviously, I think the top, important thing is egocentric data of humans doing tasks. What else would you modify on that basic statement? Jason Ma [00:08:42]: So I think data is the most important thing in robotics today, because unlike language model, there is no internet, right? So every company that’s building model, building hardware has to think about data. So there’s, roughly couple of different ways of operating here. One is that you can collect a lot of data yourself, which is what we are doing as well. Swyx [00:09:02]: You have employees here doing that. Jason Ma [00:09:04]: There are robots everywhere in the office, right? But if you think about how much data you need for robotic foundation model, I think the amount of data any individual company can collect by themselves is just nowhere near sufficient, right? It’s kind of like, you’re trying to build an internet by just having Reddit or just having Facebook. They’re great websites, a lot of users, but it’s not enough, right? So when we think about data, there has to be some sort of data acquisition happening, right? You buy data, you look at data that’s already out there. And then there’s many different tiers, right? You mentioned data quality. I think data quality in robotics is a non-stationary problem in the sense that what is high-quality data for your model changes over time. Like, when your model doesn’t know anything, like when it’s zero, any data is useful, right? You can use a lot of video data. In the case of egocentric data, I think it’s actually a very good way of pre-training robots because human data is so diverse. Like, it covers every single physical activity you can possibly imagine. And that gives robot, the model such a strong prior on how things, how the world can evolve around a embodied actor, human. But the issue with human data is that until your robot looks exactly like a human, there’s gonna be some gap between human actions and the robot actions, right? So just by training on human data, today, it’s not very likely you can just execute robot actions directly. So you still need some amount of adaptation using the robot’s own data, right? But the robot’s own data collected on a robot is gonna be much more expensive and much harder to collect. So the kind of recipe we’re thinking about is like, how do we take the largest source of data we have today, like egocentric data, to give the model a strong prior over everything physical manipulation can cover, and then combine that with a small amount of robotics data to make the robot master whatever task we’re interested in. So data quality and getting data in robotics is really, I think it’s a fascinating, multifaceted problem. But the reality is that there’s not a single winning strategy like, “Oh, here’s one kind of data. I’m only gonna collect on that,” Jason Ma [00:11:25]: Which will give you a strong foundation model. You really need to think about, “This human data covers this part of robot cognition I need. Robot data covers low-level reflex dexterity the robot also needs,” and put them into one model. And I think that’s what gives a really adaptable, really strong model at the end. Yeah. Data Partnerships and Specialized Training Examples Swyx [00:11:44]: I’ll prompt you, just for again, for the people listening who want to work with you. What, d— what data vendors do you want. This is your call for data. What- Jason Ma [00:11:55]: Yeah, no, that’s a great question. And yeah, so in our Dyna-2 blog, at the end, we actually have an email address called datapartnerships@dyna.co. So if you’re a data vendor that has a lot of high-quality, let it be egocentric data, robot data, video data, or anything you think could help robots, send it to that email. Our team will take a look, and we’ll get back to you. Swyx [00:12:16]: But at your stage, are you. You’re probably not buying any more egocentric data off the shelf, right? That you probably want to be like, “Here’s what I need. You go-” Vibhu [00:12:26]: Is there a niche that’s lacking? Swyx [00:12:28]: You need a Scale AI, you need a Mercor for doing this. I see. The custom data- Vibhu [00:12:32]: The folks that don’t work in robotics are probably thinking like, “Okay, some niche factory.” Like … you showed putting tubes in. There’s only so much data you’ll find about that but like would a lot of that help you? Jason Ma [00:12:43]: Yeah, no. If you really want to nail a task, having data from that task will certainly help you a lot, right? So for us, it’s like we still think, just a million hours of data is not enough. It’s just the beginning. Like, we showed the first model on a million-hour scale, but we need more than that right? So we are still looking at a lot of just raw, diverse data, that we can get. But we’re also thinking about how do we get more custom data either collected in-house or by our partner for really, specific niche tasks? Because I think you still need that to get to excellence that any model needs to actually be useful in the physical world, right? It’s kind of like humans, you know. If, Sean or me, we go work at Rosewood Hotel tomorrow, we are not gonna be able to make the bed the way they want, right? We need a lot of training. So that kind of data, like special data, that’s kind of like what Mercor is doing today for language model, I think will be very valuable for robotics as well. Vibhu [00:13:42]: So hotels, strap a GoPro on your employees’ heads and. Jason Ma [00:13:48]: And then there’s probably more of that. Vibhu [00:13:49]: There’s the Synthetic Data, Simulation, and the Eureka Project Swyx [00:13:50]: Put themselves in their way. Yeah. So one thing that we discussed is the closing this interview, and what’s very interesting is now you can basically fabricate environments on the fly. Have you tried that with the frontier models? What’s your experience? Are they good enough? Vibhu [00:14:06]: Are you using any world model robotic. Like, world model companies to generate these and train on them? Jason Ma [00:14:13]: So, I think generating synthetic environments, synthetic data, simulation data for robotics, it is going to be one of the next frontiers, right? ‘Cause today people have looked at egocentric data, robot data. Those are scaling, but I think synthetic data will be a new dimension of scaling. So going back to your question yeah, we have been exploring using frontier models to generate synthetic, environments for us on our data, on our environments that we care about. And surprisingly, I think now it’s at a point where this technology is actually very much worth going really deep into. So for some context, so, in my PhD, I primarily focused on simulation-based training for robotics. Back then, simulation wasn’t ready, but we had this paper called Eureka, which was the first paper taking a large language model. At the time, it’s GPT-4, which is how to self-generate environment, generate reward functions or reinforcement learning, and just do things in simulation. And at the end, I think, we had this really nice demo of the robot spinning pencils, right? That was really cool at the time. But that kind of thing was still very limited at the time, because back then the model didn’t really have good vision capability, didn’t have a innate 3D understanding, right? So it was basically just generating code and using very limited feedback from text to try to come up with new simulation environments. But today the vision capability of these frontier models are crazy. They can do real to sim, do CADing, there’s 3D reconstruction and all of that. So I think now it’s at a tipping point where Jason Ma [00:15:52]: This technology could really accelerate robotics. And for us, right, we think about that as a way to accelerate our internal progress, right? Because we’re building models, we’re building hardware. So if a frontier model can give us more data that way, like generate really tailored data for ourselves, that’s extremely useful for us. And another thing we’ve been thinking about is instead of using these models to generate 3D environments, we have also used our own world model, right, the world action model I was telling you about, because the model not only generates action, it can also generate videos. We— The model can also generate its own training data. So that becomes a self-fulfilling flywheel that I think will also be powerful. So overall, I’m just really excited about this direction because I think even though we have scaled to a million hours of data, we are deploying a bunch of robots. The robots are act— already starting to do very cool things. We’re just at the beginning, just the tip of iceberg for what is there to come. Yeah. On-Device Inference, Latency, and Model Distillation Vibhu [00:16:51]: For those on the research side, we recently had Runway on the podcast. One of their things is robotic world models. They’re, shifting a little towards there, so … nudge people to look at it. One of the questions I have about you making your own models is what is the constraints you operate in? So if you draw a parallel to language models, you see GPT-OSS 20B is very fit for your average MacBook. Then there’s a larger one that’s fit for a single GPU. Do you work in the constraints of robot, of model on on device, in cloud, a hybrid? And then how does that affect your scaling law of data? A million hours is great, but like do we just scale up parameters, data? Jason Ma [00:17:38]: No, that’s a great question. So I think what’s really different about robots versus language model and other applications is that for coding agents, language model, it’s okay if it’s— it has latency, right? Well today, whenever I ask ChatGPT, it takes like couple of seconds before it spits out anything. But for robots the inference latency has to be very short, right? The robot needs to act. Like, it can’t just hold a knife and not do anything for three seconds. That’s gonna freak people out, right? Vibhu [00:18:07]: Yeah, we saw someone put their real hand under a knife. Jason Ma [00:18:10]: Our model’s, pretty smart, so that’s okay. But in general if you think about very dynamic tasks, like for example, you want your robot to hold a I don’t know, a tennis racket and juggle the ball, right? It’s just very dynamic, real reactive. You can’t just like. The physics, gravity doesn’t wait for you, right? So for that reason, robotics model needs to be able to inference very fast. And the fastest way to do that is by serving on-prem, like on device, right? Because if you call a model- Swyx [00:18:39]: Network latency. Jason Ma [00:18:40]: There’s no guarantee- Vibhu [00:18:41]: Self-drive a car. Jason Ma [00:18:42]: There’s no guarantee, right? Like, so for that reason, the model that gets deployed eventually has to be of reasonable size that can be served locally. But that doesn’t mean that the initial model you train also has to be small, right? Like in language model- Vibhu [00:18:57]: You can distill. Jason Ma [00:18:58]: People do distillation, right? Like, the best way to make a small model very smart is by doing distillation, right? You train the biggest model, then you distill, right? So I think in robotics, we’re getting there, but I think that’s what people are going to converge on. Yeah. Vibhu [00:19:14]: How about inference? You have your own inference stack or. A lot of this is architecture. You’ve pulled diffusion and whatnot. I’m guessing you can pull off of something. Anything you wanna share? Jason Ma [00:19:26]: So we build our own inference stack for whatever model we deploy, because that’s— like I was saying latency is so important. So owning the whole stack is extremely important for robotics, right? You want to optimize the inference speed for the kind of model you’re running, and there’s a lot of work in there. So that’s what we do. Building the Full Robotics Stack: Sensors and Actuators Swyx [00:19:45]: You’re really full stack, like- Everything from the actuators all the way to in the industrial design ID, which I- Didn’t really know as a acronym. Obviously to the models and data as well. Vibhu [00:19:57]: I’m curious are these your own actuators, or are they. How much of this is your own? Like, of course, the design, it’s not like humanoid- Actuators, like how far down the robotics stack? Jason Ma [00:20:08]: So the way we think about, what we need to own versus what we can buy is like if the Input-output and of a component is very clear, and like there’s already extremely good mature solution, then there’s no point of building in-house. For example, on this robot, you see the LiDARs, right? So those, black circle, those are LiDARs to help the robot detect obstacle, navigate surroundings. So that’s a very mature technology that people have been using for now decades. It’s on self-driving car. So we don’t need to build LiDAR from scratch, right? Same goes with some cameras. But for anything that we think is extremely crucial for the whole system’s performance at the end, our vision is to be able to own that and build that ourselves. So one thing is, you mentioned actuator. So that’s something we’re working on and we’re going to own ourselves. The reason is that like, the quality and how you design the actuator really matters for how well you can model the robot, right? Actuator is what drives the robot. To be able to model your robot very well in simulation or to do any kind of modeling, you need to select actuators very good that can actually be easily modelable. So that’s what we care about eventually. So we’re gonna own that. Same thing with the robot’s proportion. This robot’s proportion is we measure it against real people. Why do we do that? ‘Cause we’re pre-training on human data. Swyx [00:21:36]: Oh, yeah. Jason Ma [00:21:36]: Best transfer, right? So there’s a lot of these kind of decision that goes into hardware that’s very much tied to like. Because eventually, it’s hardware that carries intelligence. Intelligence is the extremely important thing. We want to make sure the hardware serves for that. Swyx [00:21:53]: I would just highlight, I don’t know if this is relevant to you, but one of the most interesting robotics discussions I’ve had is someone who was very stressed out about actuators and specifically magnets, ‘cause apparently we don’t make magnets in the US. Manufacturing, Rare-Earth Magnets, and Global Supply Chains Jason Ma [00:22:06]: No, we don’t. Swyx [00:22:07]: And there’s only two countries that make magnets. Jason Ma [00:22:09]: Rare earth material. Swyx [00:22:10]: Rare earth, right? I don’t know what the. Wh-what’s the chemi— what’s the material? I don’t know what the thing is, but- so yeah, if anyone’s interested in that’s, apparently a bottleneck that we have. Jason Ma [00:22:20]: No, not bottleneck. Swyx [00:22:21]: It’s a bottleneck. So what do we do? Jason Ma [00:22:23]: It’s a good question, right? I think, there’s a lot of exciting discussions on bringing manufacturing back to the US, but for robots especially, that’s actually much harder than what it seems. And I would say even now, there isn’t a company in the US that’s truly building everything from scratch in the US, right? Like, even when they say they assemble robot, they build whatever they’re actually doing in the US, they’re still sourcing their raw materials from other places in the world. And I think that’s something to really be aware of as a robot builder, right? Like, I think, like as a full-stack robotics company, we realized just how long the supply chain is and how long the whole problem is. It’s actually extremely hard. And I think these days, a lot of the discussion centers around a robot foundation model data, but I think hardware and just how hard it is to build good hardware is very under-emphasized. But I think that’s gonna be extremely important. Swyx [00:23:27]: This is a platform, right? Why Dyna Co-Designs Its Hardware and Models Jason Ma [00:23:29]: Platform, yeah. Swyx [00:23:30]: There are some companies that choose to be, let’s call it platform-less. They only do the model, and they will say, “We deploy on any platform.” We deploy on Optimus. Vibhu [00:23:37]: Off-the-shelf robotics. Swyx [00:23:38]: And so, it’s a choice, right? Like, obviously, you own everything, so you can do that. Do you see yourself building more in the US, or do you see building your own global supply chain? What’s the direction that is likely? Jason Ma [00:23:52]: So we are currently exploring many different options, right? Because with global supply chain, then there is some, geopolitical things, right? Swyx [00:24:02]: Shipping. Jason Ma [00:24:02]: Shipping. Also shipping delays and all that stuff. Vibhu [00:24:04]: Literal ships for robots. Jason Ma [00:24:06]: And in the US, it’s just that going from zero to one will take some time, right? So we’re trying to think about a solution that can both allow us to build more in the US while leveraging global supply chain, right? But I do think, going back to your previous question on some companies choose to just build model, we build everything, I think it’s very important to get this right. I feel that for robotics, the hard thing is. Like building the whole system. What are the necessary things to build a whole system? Like, previously, I was at DeepMind, I was at NVIDIA, primarily just building models, and I saw the upper bound of the system when you don’t control the hardware, when you don’t get to optimize that right? Because if you think about the value creation for robots, eventually robots are here to deliver a service to solve some physical tasks. So if you wanna solve physical tasks, you wanna be able to optimize everything, and that’s important. The Semi-Humanoid Robot: Wheels, Torso Movement, and Dexterity Vibhu [00:25:02]: We have the robot. You gotta tell us about the design. Your own custom platform. What do you call this? Jason Ma [00:25:11]: What do we call it? Vibhu [00:25:12]: Yeah, so it’s not humanoid. It’s very smooth, but what’s the what’s the rotating arm? Jason Ma [00:25:16]: Yeah, so we think of this as generally like a semi-humanoid. So basically, the upper body is, like a humanoid. It’s got, of course, shoulder, got arms. It also got four degrees of freedom on the waist. So you can basically do all the upper body motion that a human can do. But it’s a semi-humanoid because the lower body is wheels. All right, so why do we choose wheels? Because I think there is a difference. There’s, optimal practicality versus performance trade-off. I think with legs, the energy con— the energy consumption would be a lot higher. It would be a lot more unstable. Safety will be extremely hard to guarantee. So right now, for legged robots, there’s actually no guarantee that the robot will stay upright, balanced the entire time. I’m sure you guys have seen a lot of those, robot dancing videos. Like the robot dancing thing. Swyx [00:26:08]: Seeing dancing, yeah. They all, they fall over very easily. Vibhu [00:26:10]: No, but you also see the demos that you can tell are not production, where you can box the robot and you can push it over and it’s very good. But that robot is just good at balance, right? Like- there’s a. Swyx [00:26:21]: I think the more interesting thing that you guys have innovated. So we have, one of the prototypes, which is the Mewtwo back here. Jason Ma [00:26:29]: You can call it that. Swyx [00:26:30]: This is just like an up-down, axis, and you’ve chosen to then move towards something like this which, has the ability to lean. And we’re gonna show the laundry demo where you have to lean into machines. Right? That’s another degree of freedom that I don’t even have the words for it. It’s not pitch, it’s not yaw. It’s something else. Jason Ma [00:26:47]: So yeah, how did we think about that right? Like,. So actually, it’s very used for exercise. Like, I think sometimes, a couple years ago when I was exercising, I accidentally like, pulled a muscle. Right? I’m sure you guys have that experience too, right? Then the next few days you just couldn’t move, or like you pull it where you slept in the wrong position, so your neck is very stiff. We have all experienced that. And then whenever you experience that you kind of realize, wow, so many muscles, so many degrees of freedom that we use in our daily life that we take for granted. But when it’s disabled it’s very awkward for you to do some tasks that you feel are very natural, right? So that’s also how we think about when we design robots. When you have a— this kind of design, which is this purely elevator, could only go up and down, we realize a lot of the human torso movement, like we use our waist, back a lot for day-to-day physical activity, right? Even if I wanna get this bottle I’m not just moving my arms. It’s actually very strange for me if I have to intentionally think about fixing my upper body. I would always do this right? So there’s just a lot of subconscious way that humans move their body that I think will be equally useful if robot has a degree of freedom. And if you further think about, okay, we want to learn from human data. Like, humans are moving their torso all the time. You wanna be able to ingest that into the model to control the robot. But if you have a form factor that doesn’t allow for that then the transfer becomes less and the robot becomes less dexterous and it’s just more awkward. Transferring Human Pretraining to New Robot Hardware Vibhu [00:28:22]: What’s the data labeling side of this? Like, I— you’ve seen people,. Is this the last post-training fine-tuning side of actually the hour of using the robot tele-operated or remote-controlled mapping motion? Or does some of it generalize over? Jason Ma [00:28:41]: When you say labeling, you mean? Vibhu [00:28:43]: Like, taking the model you have that predicts state to mapping it to your specific hardware. Jason Ma [00:28:50]: Oh, yeah. It generalizes very well. So for all the demos that I have shown you on the new robot, ‘cause the new robot, we, it got ready not so long ago. So we quite literally do not have a lot of data compared to the stationary arms we showed you, which had much more data, right? But a new robot, the model has not seen this in pre-training, in some of our pre-trained model. It’s able to learn the task that you saw very quickly. And I credit a lot of that to like, even before the hardware is ready, we already committed to pre-training on humans because we knew at some point our robots will be like human. You can get ahead on the training side while hardware is getting ready. And I think now we’re seeing that the transfer is actually there and is actually very helpful. Evaluating New Skills and Learning from Real-World Feedback Vibhu [00:29:35]: Talk about the eval side of this. So you can have predictions, you can have it do stuff, and every now and then we see it miss stuff. You test on very niche things as well. It’s like filling a pill bottle. How long does that process take? How do you think about the aspect of actually deploying on a new task, evaling it, iterating? What does that look like? Jason Ma [00:29:56]: Yeah, so if we wanna learn a new task, we basically do a little bit of robot data collection. Then the model, these- Swyx [00:30:04]: What is a little bit like? Jason Ma [00:30:05]: Yeah, like couple hours. Yeah, we’re— In some of the tasks, like just tens of minutes, right? Yeah. And then- Swyx [00:30:11]: The chopping one was 45 minutes. Vibhu [00:30:13]: The open the fridge was on- Swyx [00:30:14]: And that’s an interview— That’s like an onboarding task for one of your engineers. Jason Ma [00:30:18]: So,. Vibhu [00:30:20]: Fun thing if you wanna work here, you know. Find the task, have the robot do it. Jason Ma [00:30:24]: Pitch me a new task and I’ll come to the office, collect some data, train a model and see what happens. Vibhu [00:30:29]: Tie your shoes. Jason Ma [00:30:31]: Truly, it’s tying. Yeah, that would be cool. But yeah. So, you know. A little, a small amount of data collected, train a model, then we just deploy the model in the real world. And then we look at the performance, then- Vibhu [00:30:41]: To fill in collected means you are— you have a person actually operating- Jason Ma [00:30:46]: Operating. Vibhu [00:30:48]: Doing the task for a bit. And then you train? And it does okay, you improve. How do you measure? Jason Ma [00:30:56]: So when you’re training the model, there’s, certain metrics you can look at right? Just like training a model, it converges nicely. Now, after that for robotics today, we just run the model in the real world, right, on the same setup that the data is collected to see how the model does. Sometimes the model just works great out of the box, right? You don’t really need to do much more. But when the model’s maybe like seventy percent, eighty percent there, then you see how the model behaves. You figure out what it’s not good at. Then you can collect a bit more data, then iterate, right? I think of this as the robotics version of reinforcement learning from human feedback, right? The robot rolls out. You can score it good, bad S- somewhat good. And then that data, the robot’s own experience can be used to train the model. And you can also just collect more data yourself to train a model, right? Eventually, our goal is like, this robot is gonna be our platform. Anyone should be able to train tasks on it. Long-Horizon Tasks and the Bottlenecks to General Robotics Vibhu [00:31:59]: I wanna get a bit of a prediction and timeline to where that goes. Right now, the tasks are, somewhat simple, like- Take laundry out. It’s a towel. You can’t crush it. Chop some food. There’s also the side of like, okay, set up this filming studio, right? Move stuff around, bring a table, set up lights. I think- Swyx [00:32:21]: Manage my data center. And also, ref— like, recharge another robot. Vibhu [00:32:29]: When do we see the factory or what do we need to scale up? Is it model? Is it everything? It seems like your hardware is set for that but where do we see it go to a point where I can go from instead of just cut one thing to, “Okay, here’s a recipe.” Jason Ma [00:32:49]: I would say to get to truly general-purpose robots like basically a robot or a model that does anything, like- Vibhu [00:32:58]: Not that. Like, okay, so to keep it somewhat grounded on a technical level, like- when do we start to see us pushing that feedback, right? So- Jason Ma [00:33:06]: I see. Vibhu [00:33:06]: Instead of very simple chopping- Maybe a five to ten-minute sequence, right? Where now the eval step, it can break at many more points. Instead of just fill one pill bottle- Ten different pills all in a sequence, right? What’s limiting us? What are we pushing on? Jason Ma [00:33:20]: Yeah, I think. Yeah, I think a couple of things. One is that the laundry demo that you have seen, yeah, it’s gonna be one hour to finish a whole loop, right? So the longest duration the robot can do a full job is already in the hour range. Right? But to be able to do that for any task, I think the bottleneck is coming back to data and hardware, right? So for some of the tasks, for example, setting up the space, you might need more than a the parallel jaw gripper, right? You might need something more dexterous, like a hand, like a human hand, right? But then if you wanna train a model on the hand, then you’re bottlenecked by the hardware stability. Like, hand— Today, the best hands, dexterous hands are still not, durable enough. They overheat pretty quickly, right? So that becomes a bottleneck, right? Like, you— We— you quite literally have to put a ice bag- Swyx [00:34:15]: Ice. To cool. Jason Ma [00:34:16]: Human. Vibhu [00:34:16]: We’re not just auto-researching, make better model we have. We have hardware limitations. Jason Ma [00:34:20]: Yeah, so hardware limitation is a big thing. But then if hardware is limited, then that will slow down everything, right? Because to know that you’re making progress on any task, you eventually have to eval on the hardware, right? So then without the eval being very spontaneous, very fast, that also limits your research progress, right? Because then how do we collect the right data, right? I think, how do we collect the right data to do extremely complex, like setting up this studio, right? Because you can imagine, like today, most of the data is vision-based, right? It’s like video streams and some, encoding of your hand motion where the robot’s, joints. But Humans have a lot more sensors. We hear things. We feel things. Swyx [00:35:05]: Smell. Jason Ma [00:35:06]: Yeah, you smell things, right? So we subconsciously use all of those to help us be so good at manipulating the physical world. But today if we’re not capturing that at all, then even when we scale to millions of hours, you might just be missing critical dimensions of the task, so you’ll never be able to solve the task, right? So I think those are what I consider what’s dragging on the timeline. But for tasks or for workflows that you can collect data today to high fidelity, then I don’t ne— I don’t necessarily think there is a fundamental bottleneck, right? Just like what we are demonstrating, to the public this week. We have a physical agent that can do the entire laundry workflow, right, as a human would, right? Because for that task, we don’t really have like, oh, you actually need more than a parallel jaw gripper. You actually need some sensing modality that’s just not available today, right? So I do think the biggest bottleneck To have a much more general thing is still hardware and data. Real-World Deployments: Best Western and Din Tai Fung Swyx [00:36:06]: I want to take this chance to talk— let you brag about your customers and partners. You have some announced, relationships. We can start with Best Western and then maybe some of the others that you’re, that you’re proud of. Cool stories, anything like that. Jason Ma [00:36:20]: So we have a deployment blog post, on our website that goes into much more detail. I really recommend watching the video because I think the video is- Swyx [00:36:29]: Which one? The Best Western one? Jason Ma [00:36:30]: No, we have one video for all the customers we’re working with. It’s a really nice video. It shows what we’re doing. And yeah, I think it’s great. But yeah, we have customers, Best Western. That’s in the hotel space. We fold a lot of laundry towels for them. Every hotel needs it, every gym needs it, every fitness center needs it. - Swyx [00:36:51]: What’s the deployment so far? How— Like, where can I go to— Which Best Western do I go to see it? Jason Ma [00:36:56]: So if you wanna go somewhere, I actually recommend going to our other deployment, Din Tai Fung. Have you guys been to- Vibhu [00:37:04]: Very thin wrapper. Swyx [00:37:05]: We should have filmed there. Jason Ma [00:37:09]: Just filmed there. Vibhu [00:37:10]: The B-roll. Jason Ma [00:37:11]: But in Din Tai Fung if you go to Din Tai Fung or other somewhat upscale restaurant, there’s napkins on your table, right? So our robots today fold thousands of napkins for many different locations, many different Din Tai Fung locations in the United States. So that’s actually our biggest scaled customer, right? So I wanna make a distinction here. Today, there’s a lot of robotics companies that’s talking about deployments, talking about pilots. But what’s really hard is not putting your robot in one location or doing a pilot. What’s really hard is that the customers believe or validate that your robot creates enough value that they wanna deploy your robots across many of their sites. So that’s what’s happened for us with Din Tai Fung, which, to the best of my knowledge, hasn’t really happened for other companies doing similar general purpose robots. So at Din Tai Fung, our robots fold thousands of napkins per day. It’s — The quality standard is extremely high, ‘cause they want like, okay, the second fold or the seam of the napkin is only like a couple centimeters below the I don’t even know how you call it, the pocket, so you can stick the chopsticks in. So it’s actually very fine-grained, high-precision task. I can show you. Vibhu [00:38:26]: At some level, that’s what robotics are good for robots are good for too, right? Humans are not the most consistent- Especially in small details, whereas a robot can somewhat do it perfectly. It’s interesting that’s the example you bring for general purpose robotics versus, at some level, I think people would assume- you can have a specialized robot that will fold napkins perfectly to the exact, millimeter as opposed to something like this but. Jason Ma [00:38:53]: Yeah, I’m sure, maybe you can, right? But the hard thing about manipulating deformable object, right, like napkin, towels, everything’s- Deformable. There’s just infinite- infinitely many possible configuration. So that’s really hard for a specialized robot, right? And what we find is that by developing a general purpose model in a robot and adapting it to these use cases, you can actually get to a production quality faster. And what’s really nice is that now that Din Tai Fung has scaled, has signed a much bigger contract with us, they not only want our robots to fold napkins. Now they want our robots cut. That’s why we had the- Example, to cut food to the- Swyx [00:39:31]: Is that actually the second use case? Jason Ma [00:39:33]: That’s one of the use case they are thinking. Din Tai Fung needs to cut so many vegetables per day. Swyx [00:39:38]: They need to do the dumplings. Jason Ma [00:39:39]: Exactly. To the fold. That’s the final boss. That’s- Vibhu [00:39:41]: That’s the final one. Swyx [00:39:43]: I think you can. I think you have the dexterity and the precision to do this. Vibhu [00:39:46]: You have a little robot. Swyx [00:39:47]: But no, don’t break the dumplings. Vibhu [00:39:50]: That’s the obvious benefit is you can adapt them anymore. Generalist Robotics, Speed, and Consistency at Scale Vibhu [00:39:54]: I think the other thing you really touch on is the speed, right? To make a custom napkin folding with the exact ply, whatever- you have to make the machine. You can’t just Amazon this. But this can do it pretty fast, right? Jason Ma [00:40:07]: Yeah, this can do it ex— very fast. And now it’s actually al— it’s at human parity. And this robot doesn’t get tired, doesn’t need to you know. You can. And I think I really like the fact that you mentioned consistency, right? Like, one issue with Din Tai Fung is like, their LA location with New York location, Seattle location, the they fold napkins slightly differently, but from their perspective, they want consistency. But that’s exactly what these models are good at, ‘cause models are, just, it’s a set of weights. You can just put the weights in the different robots across different- Vibhu [00:40:43]: You can OTA update them as well. Jason Ma [00:40:45]: Yeah, you can just update all of them at once. It just. Once it works, I think it’s truly, like- Incredible. Vibhu [00:40:52]: Final boss is Cheesecake Factory. If the story there, they’re from scratch. Everything is very consistent, down to the measured gram. Every sauce is made. Like, anywhere you go in the world, you’ll have the exact same thing. If you don’t know, you don’t know. But that’s the that’s the final. The Bitter Lesson of Robotics: Scale the Right Data Swyx [00:41:07]: The term that comes to mind is kind of like bitter lesson for robotics, right? You, instead of the specialized robots, which is a lot of industrial engineering, you build a generalized platform that can- Do a last-mile fine-tuning and- Vibhu [00:41:18]: That’s right. Swyx [00:41:19]: And do all those things. Vibhu [00:41:20]: Give the expert add-on outside of your. What is more bitter lesson robotics? Jason Ma [00:41:25]: Yeah, I think there’s several bitter lessons for robotics. One is that robotics is going to scale just like any other domains that machine learning has solved, right? So what does that mean? That means having as much data as possible. But in robotics, the one thing that’s a lot harder is what is the right data is much harder to figure out than other domains, right? Language is text. In video games, just video game data. But for robotics what sensors you choose determine what kind of data you have, right? But if you have the right set of sensors and just scale that data, I think you’ll get predictable return on model performance. So in that way, robotics isn’t so different. So that’s the bitter lesson. As a corollary of that is that like there’s a lot of research in robotics that’s coming out with very specific priors. Like, for example, we need to make the robot see objects as they are, draw some boxes. That will give robot better perception, right? But I think the bitter lesson here is that just keep the algorithm simpler and scale the right kind of data. Then generalization, better behavior will emerge. So that’s not so different. And the second. I think that’s the main bitter lesson, which is at the end of the day, scaling will work, but in robotics, to scale and how to scale is just much harder ‘cause there is no internet. You have to come up with your hardware, come up with the sensors, get all of those right, and then scale. Then I think,. Humanoids, Practical Iteration, and the Path to Generality Vibhu [00:42:53]: There’s the argument that the world is very made for humans. It should be a human, right? As hard of a hardware problem that is, think ten, twenty, a hundred, two hundred years down the line, can we make a really efficient human? But you have to be practical with what we have now, right? Jason Ma [00:43:12]: So the way I think about it is that yes, eventually the robot should. If we wanna build a general-purpose robot, right, like a machine that can be adapted to as many use cases as possible, I think human form factor will be the best one, just because that’s what we have been doing, for ages, right? But I think the best way to actually build a humanoid robot is to take an iterative approach. Because robotic is so hard, the whole problem, the whole stack is so long, it’s really hard to know a priori what’s the right decision to make, right? And because hardware decision is much more expensive and much more costly, just ‘cause hardware iteration is a lot slower, you actually want to take an incremental iterative approach, not going all the way to the final form factor. Because the chances are the thing you build actually doesn’t last. It’s not good enough. So you just end up scratching it anyway, you know. Like, it’s public news Optimus, already gone through many iterations, and they had to scratch their designs, right? And I think by iterating with a semi-humanoid form factor and actually putting them out to real customers or in getting models really deployed, you get that feedback loop that you wouldn’t get if you’re just trying to build like, warehouse humanoid and you spend like five, ten years building it. I think the iterative approach will actually get us closer to the final robot faster. Vibhu [00:44:33]: And I will say, for those listening and not watching, it’s probably the smoothest robot we’ve seen. Like- Continuous Action Spaces and the Importance of Context Vibhu [00:44:38]: … every humanoid you’ve seen is jerky and even humans don’t walk as smooth as this thing. Swyx [00:44:43]: Because, yeah, the model is. Can move every single motor at once. Vibhu [00:44:48]: In more than two cohort, yeah. Jason Ma [00:44:50]: Yeah, and that’s actually a very hard problem, because if you just think about the model, it’s outputting action. There’s the action, dimension, right? The bigger the dimension is, the harder to fit, the model to the data. But here, the action space is quite large, but we did very good job to make sure the model fits well and gives you a smooth- Swyx [00:45:10]: Can you bound the order of magnitude of the action space, or is that- Jason Ma [00:45:14]: Yeah, so it’s on the order of, about a hundred action dimensions. Swyx [00:45:19]: Yeah, and these are all continuou- continuous, right? Jason Ma [00:45:21]: Continuous, right. So the model is just basically predicting at very high frequency, like tens, like at least fifty-dimensional vector, like ten, twenty times a second to get that continuous motion. Swyx [00:45:34]: And potentially predicting one to two seconds out, so that is another hundred frames or whatever. Jason Ma [00:45:39]: Of course. Vibhu [00:45:40]: There’s a bit of a history, similar to context of previous state, I guess. Jason Ma [00:45:45]: So context is a very important thing in robotics, right? Because otherwise, if you’re just making decision based on the current observation, sometimes it’s really hard to tell what to do next, right? For example if you think about opening a microwave, like in the middle part, it’s unclear whether or not you’re- Vibhu [00:46:01]: Closing Jason Ma [00:46:01]: … closing or trying to open it, right? So context is also really important. Swyx [00:46:05]: And I have a screenshot of the fridge demo where it is, there’s agentic planning and tool holding and all those things. So we can show that for listeners. Vibhu [00:46:13]: I think that’s an interesting side. After the model- Agentic Harnesses and Planning Physical Workflows Vibhu [00:46:16]: … how do you wrap it around into agentic harness? Like, what is- Swyx [00:46:22]: Claude Code Vibhu [00:46:22]: … Claude Code deployment? Claude Code UI. You have a lot of cool UIs, but what goes into wrapping model output towards final thing? Is this custom per use case? Is it you have your own SDK? Jason Ma [00:46:37]: So, eventually we will have our own SDK, but the way we think about is we want a general harness layer for robotics foundation model. Today, that is our own model, right? The way I think about is for any Real task, long task in the physical world, there is a lot of a high-level decision-making you have to do, right? It’s not just like robot, only reasoning about the physical world in the action, continuous trajectories, right? Because that’s a very low level, the thing you’re actually executing in the physical world, but that’s not the intent. But like if. When we are doing decision-making, we think about steps of a recipe. We think about, oh I finished this I need to do that. While I’m waiting for this part to finish, I need to go somewhere else to do something else. There’s a lot of high-level cognition, decision-making that’s happening. And I think for robots to handle even, the laundry task we are showing you, it has to have that capability. Because, it needs to reason that okay, the washer is running, so I should go do something else while the washer’s finishing. But now the washer is done, I should take, I should take the towels from the washer and put it in dryer immediately, right? Because if not, then that becomes a bottleneck in the whole workflow, right? So there is a lot of reasoning that needs to happen for robotics. And I think in theory, you could just, try to learn that with a low-level model that’s outputting actions, but it’ll be extremely inefficient. So that is why having a hierarchical system, like putting a harness, like an agentic system around our world action model is what allow the model to compose different capabilities, different skills to solve a much longer horizon task. It’s very much like in language model, right? Like two years ago, three years ago, the model was only good at autocomplete. Like, humans have to tap to get the model to keep spitting out code. But today, just an agentic system just carries the end-to-end task. And that’s. I, and I think that’s important because I think today in robotics, people are still thinking about autonomy at the very task level like one minute, thirty-second task. But really, the value is about tasks or workflows that go on unsupervised for hours. And that’s what we’re building towards. And that’s why I think thinking about. The robotics problem, not just as a modeling problem, but rather as a system problem, you need good agent, good harness engineer, good model, good hardware, everything. It’s like how we think general-purpose robots ought to be solved. How Coding Agents Accelerate Robotics Research Vibhu [00:49:07]: Do you guys see benefits from language model coding tools getting better? So new Opus 5.5, new Astra. Do you have language models in your agent harness? How does AGI being developed in language model space affect you guys? Jason Ma [00:49:24]: No. Yeah, no, absolutely. Like, it affects us very deeply in many ways. One is that we are extremely AI-native company, right? Like, coding agents, all of that is a very fundamental part of our work, and we’re very welcoming of that. Like, whenever there’s a new model, we’re the first one to test it, right? Like, we being. Like, when GPT-6 came out, we had a company-wide hackathon the same week, and the thing that our engineers built was incredible. And many of them are— Many of the features we built is already in main, in production, right? So we really like using coding agents to accelerate our work. Swyx [00:50:00]: Just for the people interested, anything surprising in GPT-6 that you found? Jason Ma [00:50:05]: … it’s about the ability for it to construct virtual environments, right? Turns dissemination. We talked that twenty minutes ago. I think that’s really exciting. Vibhu [00:50:17]: It’s interesting. There were so many CAD, Zillow to 3D-ish. Swyx [00:50:21]: He lost the hackathon to the CAD, - Vibhu [00:50:24]: I won the. I did the CAD b******t. Other way. Swyx [00:50:27]: No. Oh. Vibhu [00:50:28]: That was. I won a GPT hackathon just for fun. I was like, “I know nothing CAD.” Might as well play around with it ‘cause every demo is doing it. I’m like, “It’s gonna be garbage.” And I’m like, “Well, it’s kinda grounded, it’s kinda good.” But it’s just hackathon stuff. Deployment Milestones and Competing Robotics Strategies Vibhu [00:50:45]:. Swyx [00:50:45]: Cool. I wa— I was gonna round out, some of the use cases and then go into a little bit of company culture and your personal background. Vibhu [00:50:52]: I have two technical questions. One is, are there any goals you wanna set for yourself, like six months, one year, two year timeline that you see robots should be able to do, fill in the blank, that you’re kinda working towards? Jason Ma [00:51:09]: Yeah, in the six months to one year frame, our goal is definitely scaling up our robots and our model and truly getting them to deploy- Vibhu [00:51:18]: Like a task. Jason Ma [00:51:18]: … completely different. Vibhu [00:51:19]: Like, right now it’s cutting or opening a fridge. Is there. Like, do you set yourself to by this timeline, we should, to stay on track, be able to do whatever? Jason Ma [00:51:29]: I think, in terms of deployments, we’re exploring many different industries. There isn’t a particular task we think we have to nail, right? Because our goal is to build a general model, a general platform, and we think of each different task as validation of our platform as a way, as a wedge for us to figure out how to build everything better. So today, we are doing a lot of that in laundry, in restaurants. We have already deployed tens of robots, but our goal next year is overall just deploying hundreds of robots. Vibhu [00:52:02]: My part two on the last technical question is, how do you see the rest of the industry? So fill in for people, what other approaches are people taking to world models? Why are they wrong? What is different but good about their approaches as well? Just what is the landscape of robotic world models in this space and why— how have you come to your current? Jason Ma [00:52:25]: No, that’s a great question. So I think robotics is the most exciting space today, and there are just so many, amazing companies that I truly respect. They’ve been doing great frontier work like us, and it’s very exciting. And I think what we are seeing today is that there’s still many different approaches to robotics. Like, we believe that hardware needs to be built in-house. We need to own the whole, chain. We believe that scaling human data is extremely important. But there are companies that’s betting on just scaling robots’ data or scaling some sort of intermediate data collection devices, right? All of them are in play, and I think it’s different approaches. We’ll just see what happens. I think right now, it’s still a bit early to tell, but we feel pretty good about the way we’re building things just because we as a company, culture-wise, mission-wise, we’re not here to just build a model. We’re here to truly get robots deployed. So we deploy as much as possible, work on the hard problems. So we identify problems much earlier on. So then I think that really helps us identify what the true bottlenecks are and then solve them. And I think for folks, for people who are only working on one part of the problem, it’s kind of like fog of war. You don’t really see the whole picture, and you might be building something that’s extremely cool technologically, but may not be what people need or want at the end, right? I think there’s a whole graveyard of robotics company, and I think all of them had very shiny, very cool robots, but just figuring out what people actually want is actually. It’s very easy to say “Build something people want.” everyone says that but it’s actually really hard to execute a robotics company. World Action Models vs. Vision-Language-Action Models Vibhu [00:54:07]: On the technical side, you have your world action model. Is that standard across industry? Is there other directions people are taking? Jason Ma [00:54:15]: Yeah, I would say that’s also not standard. So we’re building world action model on top of world model. So there is many companies building world model. You mentioned Runway. They’re also getting to adapt- Vibhu [00:54:26]: Video world models. Jason Ma [00:54:27]: There are also companies building a vision language action model. Vibhu [00:54:31]: VLA. Jason Ma [00:54:31]: So that’s like taking vision language models and adapting them to robotics. So I think there’s many different ways to go about it. But I think at the end of the day what we call the models is less important than what we believe the model needs to be able to do at a first principle level. So I wanna explain that a bit. I think for robotics, the most important thing is that you need to be able to predict the future. Right. Like robotics, any physical system is fundamentally about based on the information you have at the present moment and before, what should you do next? So it’s really about predicting what comes next. So predicting robot actions is like predicting what the robot should do next. But if you think about it, robot is just a part of the world, right? Robot influences the world, but the world also influences how the robot should behave in that environment. So if you think about it this way, then the maximal, the most first principle thing you can do is just predict as much of the world that you can possibly predict, right? So that’s why we believe predicting the future is extremely important. And today, the instantiation is world action model. And VLA only predicts robot actions or some more abstract representation of the world. But whenever you’re predicting abstract representation of the world, you’re encoding your own bias into what’s important to predict. And the bigger lesson tells you, let’s remove human biases. Let’s just take the most raw representation, the camera inputs, and just predict all of that right? So that’s how I think about, modeling for robotics today. Swyx [00:56:12]: So just to press you a little bit on this you’re, basically you’re saying your approach is better than the VLA, right? Because you’re emphasizing prediction. I fully buy that. I— Like, you’ve sold me on it. If you were wrong, what is the most likely number two- Beyond Vision: Tactile, Audio, and Infrared Sensing Swyx [00:56:26]: Someone else is doing? Vibhu [00:56:27]: Interesting question. Jason Ma [00:56:28]: So yeah, there’s a caveat in what I’ve said before, and I think that’s where I could be wrong, right? I said that you need to predict the world as much as possible, right? But what that doesn’t say is that does your sensor have everything about the world that you need to predict? I think I touched on this a little bit, right? Like, if you’re training a world model that’s purely based on videos, I think it will be a very powerful world model, but it may not be a sufficiently rich enough world model because you’re missing critical aspects of the world, like sound, like touch, right? So I think where we could be wrong is like, okay, I have the best world model on vision-based world model, but tomorrow someone else comes out with a vision plus tactile world model that’s just like a hundred X more data efficient just because, vision is a very high information or a highly redundant, input because, every other pixel, they don’t change that much. You can see— you can understand the world without perfect vision. But tactile, other modality might be much denser in information, right? So maybe having that predicting that would just allow you to use much less vision. So you can get to the same performance with much less compute, with much less data, right? But- Swyx [00:57:51]: I think you will be able to adapt very easily. Jason Ma [00:57:53]: No, exactly. Vibhu [00:57:53]: There’s also a level of how much data. Jason Ma [00:57:56]: Right. So the reason why I bring this up is because I think if a vision-tactile world model or vision-tactile-audio, whatever world model, is the final thing that solves robotics, then I think robotics companies will be able to do that better than video generation companies that’s trying to pivot to robotics. The reason is to understand sensing is actually very complicated. Like, we’ve been building that since the company started, so we know the bottleneck. We know how to combine them. But for— if you’re just trying to adapt a video model to robotics action, then if we were wrong, if, video model is not enough, then you don’t really have the know-how to get tactile to work very well. But we have that. Swyx [00:58:39]: This is a side question, but I think it’s a quick one. Heat seems very important. Is infrared just another color to you, or is that a. Jason Ma [00:58:47]: Yeah, it could be another- Swyx [00:58:48]: Just another color. Jason Ma [00:58:48]: It could be another color, another input to the model. Could be used in cooking scenario, actually. Like, I know companies that’s using infrared to know how cooked food is. Because that’s really hard to tell from RGB camera, right? Vibhu [00:59:01]: My very naive pushback on your last point is maybe we don’t need to understand hardware, cloud code, or Codex can just, vibe code it in. There’s a lot you can do without understanding, but of course- Swyx [00:59:15]: It’s just not in the distribution. Jason Ma’s Journey: AlphaGo, Penn, NVIDIA, DeepMind, and Dyna Swyx [00:59:16]: So I wanted to bring it a little bit to your personal story or your background. We both went to Penn. Jason Ma [00:59:24]: I just found out today. Crazy. Swyx [00:59:26]: Yes. I, my big regret is I didn’t join the self-drive, the Docker challenge. Which, and then I could have been early Waymo or something. You were at Grasp. And then you’ve also worked at Google and NVIDIA. What are the different focuses of let’s say, academia versus Google versus NVIDIA? You’ve seen all these places, right? And then that obviously caused you to say “Screw all that. I’m gonna do my own thing,” right? You could have joined OpenAI’s robotics lab. So may-just take us through chronologically, but also one thing you learned from each. Jason Ma [00:59:58]: So chronologically, yeah, maybe it’s useful to talk about how I got into AI in the beginning, right? So, as a kid, so I spent time in Japan and China. I grew up playing Go, the Go in AlphaGo. So when AlphaGo came out, I was a senior in high school, and I was mind-blown because I’ve been playing this game for many years. It’s so complicated. Like, I think before AlphaGo came out, people were like, “Okay, Go is one of the game that AI will never solve.” The search space is larger than the total number of atoms in the world. How could you possibly search for solutions in that? Then RL, reinforcement learning just cracked it, right? And I think that was how I got into AI initially. Like, I was just really interested in models or systems, agents that can self-improve, right? So when I got to Penn as a PhD student, I just really wanted to work on reinforcement learning. So I’m co-advised. Both my advisors were interested in RL at the time. One of my advisor was more in robotics. He did a postdoc at Berkeley Robotics Lab. So that’s how I got into robots. At Penn, we have GRASP Lab, I think one of the best places to do robotics. And so that’s how I got into doing RL for robotics in my PhD. And then, yeah, I did a bunch of research thinking about how to connect reinforcement learning, with human data, how to do reinforcement learning, theory in a very rigorous way. And then I went to NVIDIA. That’s when GPT-4 came out. At the time, we were very interested in just solving a pen spinning task. I don’t know why. Like, - Swyx [01:01:35]: It’s the dexter- it’s the dexterity limit, right? That you can solve Rubik’s cubes, and then you- Jason Ma [01:01:39]: At the time, I was working with, - Swyx [01:01:41]: Jinpeng Jason Ma [01:01:41]: … Jinpeng at UCO, which you guys probably also know. Like, yeah, we were just like, “Okay, let’s try to do dexterous pen spinning.” The initial idea was learning it from human videos, right? We were trying to watch humans do it. But then I realized, okay, today we don’t have a dexterous hand that can spin pencil at all. So how would I even be able to evaluate the algorithm, even if learning from human worked at all? So I thought, “Okay, we need to first try this in simulation.” Then as soon as I tried to set up a simulated environment for a robot hand with a pen, I immediately saw what the issue is. The issue is like, if I had to come up with this simulation environment, the reward function for reinforcement learning to solve pen spinning, that’s impossible. Like, I wouldn’t be able to come up with all the terms that you need to get RL to learn the right behavior. And then I was just thinking, “What if a model that can write code can do that?” That’s what became the Eureka project, right? We basically. Like, in my opinion, we had the first recursive self-improving robotic agent in simulation, ‘cause we really used that to solve a new task that no one has demonstrated before. And that allowed me to see the potential of using language model, using coding models to really accelerate robotics. So then I went to Google DeepMind, ‘cause at the time, even today, they have one of the frontier models in Gemini, right? So I was looking at how to use Gemini for robotics. But eventually I realized like, I had a lot of fun doing academic research, but there was always a question in the back of my mind “Does any of this matter?” like, when you’re working on this kind of thing in a lab you ask me, “How do we come up with so many interesting, fun tasks?” You’re basically doing your own eval. You’re grading your own homework. Like, I wanted something more real. I wanted something that could actually be used by millions of people in the world. And I felt twenty-twenty-four was when we started Dyna, like end of twenty-twenty-four. That was the right time that we can take some of these technology to actually putting them out in the real world. So that’s why Jason Ma [01:03:45]: I started Dyna with Lindon Gao and York Yang. And fast-forward two years, we built our platform, our model. Our robots are in Din Tai Fung. Go check it out and, - Vibhu [01:03:55]: Go eat. Jason Ma [01:03:56]: Yeah, go eat. It’s been a journey. And,. But what still gets me really excited is, like some of— a lot of the ideas that I temporarily abandoned when we started Dyna, because, to build a company, you have to be very practical. Like, I think simulation wasn’t ready in twenty-twenty-four. But now with like the new frontier models and what we’re seeing internally this might change. And that’s very exciting. Product-Led Research, Experimental Evals, and Company Culture Swyx [01:04:20]: And so then also let’s talk about company culture. What principles you’re building the company with. Obviously the— you’re responsible for the science and the research, agenda. And it just seems like when we meet the engineers, they are, they’re very engaged and then they have a lot of ownership. They have a lot of motivations. Vibhu [01:04:38]: I’ll say it’s interesting to see how many side projects people just work on. So some of the demos we’ve seen, it’s just the engineers that work on it were like “Yeah, this seems fun. Might as well do it.” To your point on fun evals, right here, like two feet behind the camera- Swyx [01:04:55]: Can’t talk about that. Vibhu [01:04:57]: … just the e— the eval is just there’s highlighters, four highlighters being rubber banded together, right? It’s like, who comes up with, “ yes, we need to test putting rubber bands on high.” It’s just- Swyx [01:05:07]: Fissionary-ish Vibhu [01:05:08]: … fun stuff. People are very … creative here. It’s a beautiful space. Jason Ma [01:05:12]: Yeah, I think culture. Yeah, so let’s first talk about, how we run a company, right? Like, we think of ourself as like a like a eventually like a research plus product company. It’s kind of like OpenAI where you do frontier research, but eventually all of them make their way into Codex through ChatGPT. That’s how we think about it too. We’re not here to just do open-ended whatever thing that interests us at the time. We’re always product-driven. Like, we wanna deploy our robots, our platform to a new customer. What are the technical problems we have to solve, right? We have to solve generalization. We have to solve whole body control. We have to solve how to adapt quickly. We have to solve how to make the robots follow language. We have to solve dexterity. So once all those problems are very clear, then, like. Our engineers are very capable. They’re very smart. So they just create instances of the task. They create tasks that will stress test those capabilities, right? Like the j— the grabbing a drink task is just how we test language following, right? You can just specify what you want. If the model follows intent, follows instruction, it should be able to do it. So that’s how we think about, like. At the top level, we identify what are the things we have to solve. Then we have a lot of bottom sub-project to actually drive execution to solve them. And you hire the right people. And everyone here is super passionate about robots. They’ve been doing this for a long time. They love it. And we just create a culture where it just naturally happens. And it’s a really fun place to work. The Team: Hardware, Software, Research, and Learning Vibhu [01:06:44]: What’s the split between technical research software versus hardware side of the company? Jason Ma [01:06:51]: We recently grew so much, so I don’t have the perfect number. But I would say on the hardware side, we have, I would say probably like thirty percent, forty percent of hardware, just because hardware you need a lot more people. And then we have around ten people working on models. And then we have software engineers, robotics engineer. We have a lot of very talented people on the business side. The most fun thing about building a robotics company is you see everything. Everything under the sun that could possibly be helpful will be helpful, right? And so you just get so much exposure working with so many different people from many different backgrounds who are all very passionate about robots. And I think it’s been really eye-opening for me as a founder. ‘Cause when I was a researcher at a lab or a PhD student, I was talking to researchers every day, and that was great. That was really good. I still get to do that every day, but now I also get to learn just from so many different people from different walks of life. Like, some of our people who collect data, they had no robotics experience. They were working in retail, working in some other jobs, and they came here, you know. They also became very well-trained in robotics, and I think that’s just pretty amazing to see. And I think of myself as I’m still learning, you know. I think of myself as just always learning in the robotics space, and I haven’t learned so much as I am now. Even though, you think about me now, I’m not a student anymore. I’m here running a company, managing a lot of things, but I still feel like the day-to-day learning is just so much. Dyna’s Vision and the Origin of Its Name Swyx [01:08:29]: And then just to close off, where’s Dyna going? Two years, five years, what’s, the vision? Jason Ma [01:08:37]: Yeah, I think our vision is to truly— The high-level mission is truly bring robots and intelligence, right, into the physical world. Like, actua— That means actually seeing our robots deployed thousands of customers, even more, millions of robots. That’s where we wanna get to. Vibhu [01:08:58]: What’s the what’s the name from Dyna? Dynamic? Is there a is there a story? Jason Ma [01:09:03]: Yeah, there’s many stories. So I na— I named Dyna. There were a lot of internal options. Vibhu [01:09:09]: Take the credit. Jason Ma [01:09:11]: … internal, different options. But how the name came to be was, there are two things. One is so, Turing Award winner, Richard Sutton, who was the pioneer of reinforcement learning, wrote a paper called Dyna many years ago. It’s about basically an agent that self-improves, world model. And I felt even when we started the company we weren’t doing world model yet, but I felt that’s how robotics will get solved. And now our technology direction is converging to that. So I felt that was a really neat inspiration, also because I worked in reinforcement learning, I have a lot of respect for Richard. The second thing is that it’s a bit more personal. Like, I grew up in Japan, and the year I was born, there was just a cartoon show. I don’t know if you guys have seen Ultraman. Swyx [01:10:00]: Yeah, of course. Jason Ma [01:10:01]: The yeah, the Ultraman that year was called Dyna. So, yeah, it’s a very subtle thing not people know, but I guess now everyone would- Vibhu [01:10:10]: The team is finding out too. Swyx [01:10:13]: But I think Richard would appreciate it. I don’t know if you ever talked to him, but- Jason Ma [01:10:16]: No, I’ve seen him at RL conferences. Swyx [01:10:18]: You should just be like, “Hey, this company-” Jason Ma [01:10:20]: Yeah, I’ll invite him, come- Swyx [01:10:21]: Inspired by you. Vibhu [01:10:22]: Everyone knows Richard for a better lesson, but you know. Jason Ma [01:10:24]: Yeah, also better lesson. Swyx [01:10:27]: Okay, any parting thoughts or calls to action? Closing: Deploying Real Robots and Building the Future Jason Ma [01:10:31]: Calls to action. Yeah, I think I do feel like as an industry, robotics is still very demo-oriented. Like, I have done a lot of demos in the past in the lab, even here we had to show some demos. But I think we need more people that’s truly, mission-focused on doing whatever it takes to get robots deployed, get, robotic foundation models truly integrated with hardware and seeing them at real customer sites. I think we’re a pioneer on this regard, and I wanna see more in this field. And for the audience that’s watching, if this mission inspires you, if, solving the hardest problems today is what makes you wake up every day and you wanna contribute, we’re always hiring and yeah, looking forward to that. Swyx [01:11:14]: Bay Area? Anywhere else? Jason Ma [01:11:16]: Yes, just Bay Area today. Swyx [01:11:18]: Bay Area. Jason Ma [01:11:18]: But as company grows, never say never to other locations. Yeah, but that’s what I wanna say, and I wanted to see more robots in the world. Swyx [01:11:27]: Cool. Congrats on everything. This is incredible progress for two years. Yeah. Amazing. Jason Ma [01:11:34]: Yeah, I really appreciate it. Thank you for visiting us. I hope it’s been fun. Swyx [01:11:40]: I don’t regret doing this on site. We do a lot of interviews in our studio, but this was worth it. Jason Ma [01:11:48]: I think for robotics, gotta do it on site. Vibhu [01:11:51]: For people listening in, watch the video version. We have fun B-roll. This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
出典・この記事について
- 番組
- Latent Space: The AI Engineer Podcast(Latent.Space)
- 元の回
- Dyna-2: General Purpose Physical Agents with Hour-Long Autonomy — Jason Ma, Dyna Robotics
- 配信日
- 要約作成日
- 公式サイト
- www.latent.space/podcast
この要約・解説記事は、元の音声を文字起こしした内容をもとに AI(Claude)が日本語で作成したものです。 固有名詞や数値に誤りを含む場合があるため、正確な内容は元の音声でご確認ください。制作方法について
関連エピソード
なぜ AlphaFold はタンパク質フォールディングを「解決」しなかったのか — Pushmeet Kohli(Google DeepMind)× Sal Candido(Biohub)
Latent Space: The AI Engineer Podcast
合成超知能へ――半導体から超伝導体まで:Periodic Labs の Liam Fedus と Ekin Dogus Cubuk
Latent Space: The AI Engineer Podcast

暗黙のインタラクション:ロボットや自動運転車は人間の「書かれざるルール」をどう学ぶか
Data Skeptic
ひとつの脳、あらゆる身体:Gemini Robotics 2とクロスエンボディメント、ヒューマノイドの現在地
"The Cognitive Revolution"
学界は野心のためにある — Alex Zhang(MIT)が語るRLM・ハーネス・エージェントスウォーム
Latent Space: The AI Engineer Podcast
オープンモデルとフィジカルAIの未来 ― NVIDIA Cosmos Lab のMing-Yu Liu氏に聞く
Practical AI